
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Results · 41 for “Data Processing Techniques”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Event Time vs Processing Time in Stream Processing
Event time is when an event occurs, while processing time is when it is handled.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Batch vs Stream Processing in System Design
Batch processing collects data to process later, while stream processing handles data in real-time.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Downsampling and Aggregation in Time-Series Databases
Downsampling and aggregation reduce data volume while preserving essential trends.

⚡ One HLD concept. 60 seconds. Interview ready
Stream Processing Architecture: From Events to Real-Time Insights
Stream Processing Architecture helps turn incoming events into real-time insights efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Data Warehouse Architecture: Analyzing Business Data Efficiently
Data warehouses help businesses analyze large amounts of data for better decision-making.

⚡ One HLD concept. 60 seconds. Interview ready
ETL vs ELT: Where Should Data Transformation Happen?
ETL transforms data before loading, while ELT loads raw data and transforms it later.
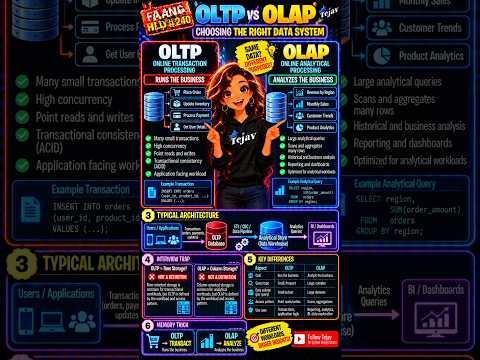
⚡ One HLD concept. 60 seconds. Interview ready
Understanding OLTP and OLAP in Database Design
OLTP handles transactions while OLAP is for data analysis and reporting.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Stateful Stream Processing: How Does It Remember?
Kafka uses state stores to remember previous events in stateful stream processing.

⚡ One HLD concept. 60 seconds. Interview ready
Change Data Capture (CDC): Real-Time Database Syncing
Change Data Capture allows real-time syncing of database changes to other systems.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Late-Arriving Events - Drop, Update, or Replay?
Late-arriving events can be dropped, updated, or routed based on system needs.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Based Partitioning: Scaling Time-Series Databases
Time-based partitioning organizes time-series data into smaller, efficient segments for better querying.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Series Data Modeling: Avoiding Cardinality Issues
Choosing the right labels in time-series data is crucial to avoid inefficiencies.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Partition Pruning Explained — Scan Less, Query Faster! ⚡
Partition pruning helps databases skip unnecessary data scans, speeding up queries.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Series Database Architecture: Storing Millions of Metrics
Time-series databases are designed to store and query time-stamped metrics efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Data Lake Architecture: Storing Big Data at Scale
Data lakes store large volumes of diverse data for analytics and processing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Retention Policies in Databases
Retention policies help manage how long data is kept in databases.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Database Indexing: How to Make Queries Fast
Database indexing speeds up data retrieval by allowing quick lookups.

⚡ One HLD concept. 60 seconds. Interview ready
API Pagination: Efficiently Handling Large Datasets
API pagination helps manage large datasets by breaking them into smaller parts.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Data Residency in High-Level Design
Data residency is crucial for compliance with laws about where data can be stored.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Penetration in System Design
Cache penetration occurs when requests for non-existent data overload the database.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Database CDC with Kafka for Real-Time Events
CDC with Kafka allows real-time updates from databases to multiple services.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Tokenization and Analyzers in Search Engines
Tokenization and analyzers help search engines process and match text effectively.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Search Engine Architecture and Its Components
Search engines collect, index, retrieve, and rank documents to provide relevant results.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.

⚡ One HLD concept. 60 seconds. Interview ready
Data Lakehouse Architecture: Combining Lakes and Warehouses
Data Lakehouse architecture merges flexible data storage with reliable analytics capabilities.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
SQL vs NoSQL: Choosing the Right Database for Your Needs
The choice between SQL and NoSQL databases depends on your application's specific needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Metrics vs Buckets Explained
Elasticsearch aggregations help summarize data using metrics for calculations and buckets for grouping.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.

⚡ One HLD concept. 60 seconds. Interview ready
Backup Strategies: Full vs Incremental vs Differential
Backup strategies include Full, Incremental, and Differential, each with unique benefits.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Safely: Reprocess Messages Without Losing Data
Kafka allows safe message reprocessing by resetting consumer positions without altering data.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Fetch & Batching: Boosting Throughput
Kafka consumers can fetch data in batches to improve throughput and reduce latency.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Streams Windowing: Tumbling vs Hopping Windows Explained
Kafka Streams uses tumbling and hopping windows for time-based data aggregation.

⚡ One HLD concept. 60 seconds. Interview ready
Tumbling vs Hopping Windows in Stream Processing
Tumbling windows are non-overlapping time segments, while hopping windows can overlap.