
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Results · 60 for “Load balancing”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Load Balancers in System Design
Load balancers distribute traffic across multiple servers to enhance performance and reliability.
⚡ One HLD concept. 60 seconds. Interview ready
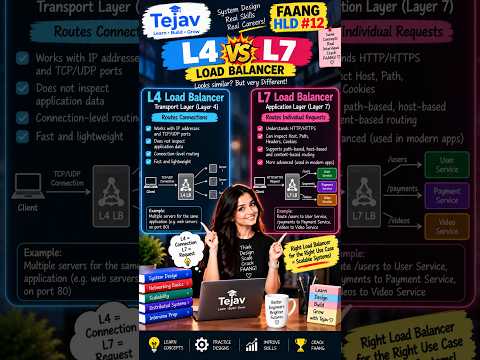
L4 vs L7 Load Balancers: Key Differences Explained
L4 and L7 load balancers differ in how they route network traffic based on layers of the OSI model.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.
⚡ One HLD concept. 60 seconds. Interview ready
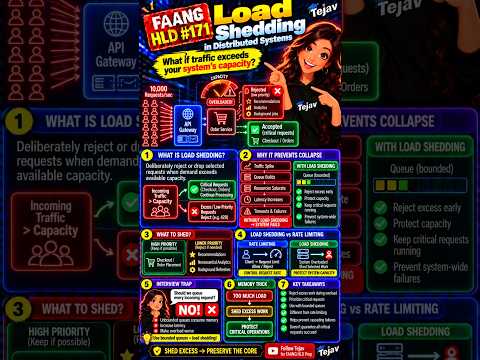
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
API Gateway vs Proxy vs Load Balancer: Key Differences
API Gateway, Proxy, and Load Balancer serve different roles in managing requests and traffic in systems.
⚡ One HLD concept. 60 seconds. Interview ready
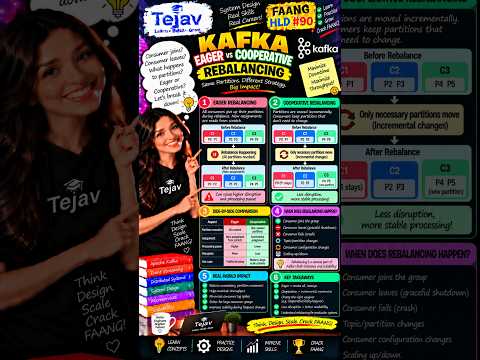
Kafka Eager vs Cooperative Rebalancing: Key Differences
Eager rebalancing revokes all assignments, while cooperative allows incremental changes.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Vertical and Horizontal Scaling in System Design
Vertical scaling means upgrading one server, while horizontal scaling means adding more servers.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Backpressure Strategies: Handling Traffic Spikes
Backpressure helps manage message flow in Kafka during traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Rebalance: Avoiding Work Loss or Duplication
Kafka rebalance can lead to lost or duplicated work if not handled carefully.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Kafka Backpressure Explained — What Happens When Consumers Can't Keep Up? 🚨
Backpressure prevents system overload by managing message processing rates in Kafka.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Keep-Alive in Networking: Efficient HTTP Connections
Keep-Alive allows reusing HTTP connections to improve efficiency and reduce overhead.
⚡ One HLD concept. 60 seconds. Interview ready
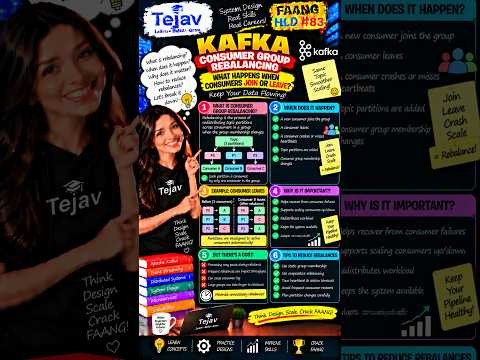
Kafka Consumer Group Rebalancing Explained
Kafka rebalances consumer groups to manage partition assignments effectively.
⚡ One HLD concept. 60 seconds. Interview ready
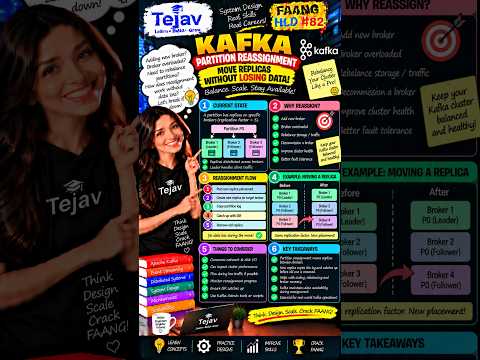
Kafka Partition Reassignment: Move Replicas Without Data Loss
Kafka Partition Reassignment moves replicas between brokers while keeping data safe.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket Rate Limiting Explained for Interviews
The Token Bucket algorithm helps manage how many requests a server can handle.
⚡ One HLD concept. 60 seconds. Interview ready
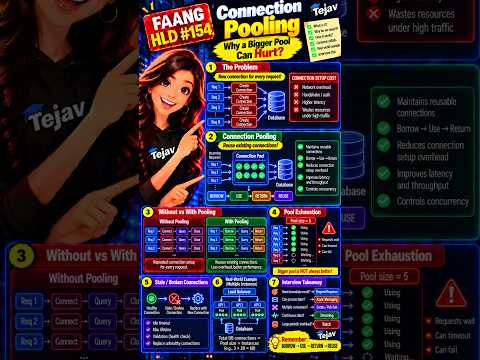
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Read Replicas in Database Scaling
Read replicas allow databases to handle more read requests by distributing them across multiple copies.
⚡ One HLD concept. 60 seconds. Interview ready
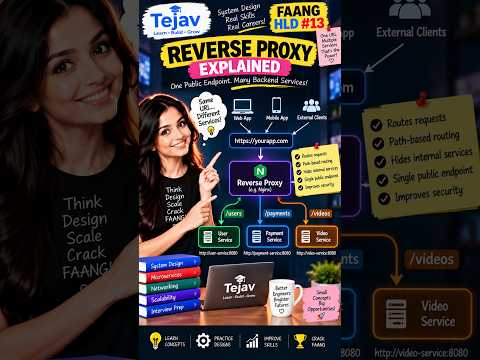
Understanding Reverse Proxy in High-Level Design
A reverse proxy routes client requests to different backend services efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Consistent Hashing: Key to Distributed Systems Scalability
Consistent hashing helps distribute data across servers with minimal movement.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Split Brain: Master Election and Quorum Explained
Elasticsearch uses master election and quorum to prevent split brain scenarios.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.
⚡ One HLD concept. 60 seconds. Interview ready
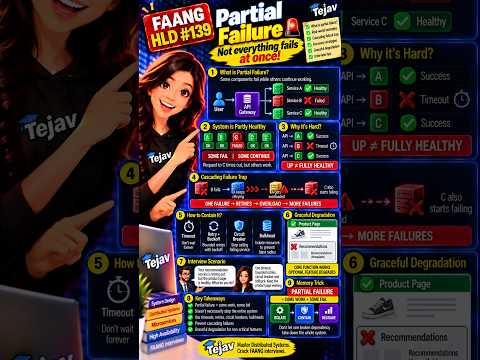
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Lag Monitoring: Prevent Production Issues
Monitoring Kafka consumer lag helps prevent production problems by ensuring consumers keep up with message traffic.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka subscribe() vs assign(): Who Controls Partition Assignment?
Kafka's subscribe() lets the group manage partitions, while assign() gives control to the application.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Rebalance Listeners in High-Level Design
Kafka Rebalance Listeners help manage state during partition changes in consumer groups.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CDN: How Cache Hits Improve Performance
A CDN speeds up web applications by caching content closer to users.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Service Discovery in Microservices Architecture
Service Discovery helps microservices locate each other dynamically without fixed IP addresses.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Pause & Resume: Managing Backpressure Smartly
Kafka consumers can pause and resume message processing to handle backpressure effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Static Membership: Reducing Unnecessary Rebalancing
Kafka's static membership allows consumers to maintain stable identities, reducing unnecessary rebalances.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Manual Partition Assignment: Using assign() for Control
Kafka's assign() method allows manual control of partition assignments for consumers.
⚡ One HLD concept. 60 seconds. Interview ready
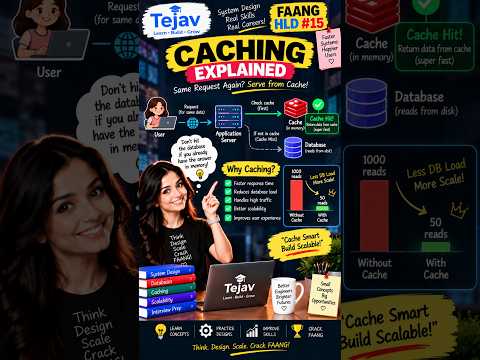
Understanding Cache Hits: Reducing Database Load
Caching helps applications respond faster by serving data from memory instead of hitting the database.
⚡ One HLD concept. 60 seconds. Interview ready
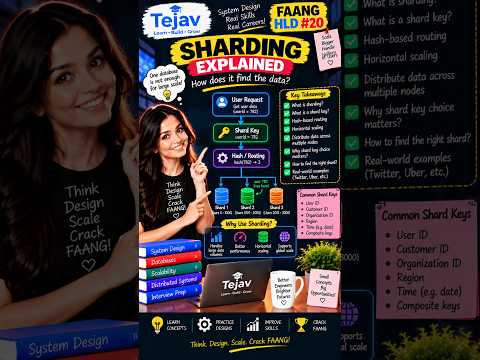
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Message Queues in Distributed Systems
Message queues allow services to communicate asynchronously, improving scalability and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Read-After-Write Consistency in Database Systems
Read-after-write consistency ensures users see their latest updates immediately.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Lag Recovery Time: How Fast Can Consumers Catch Up?
Kafka lag recovery time is how fast consumers can process backlogged messages.
⚡ One HLD concept. 60 seconds. Interview ready
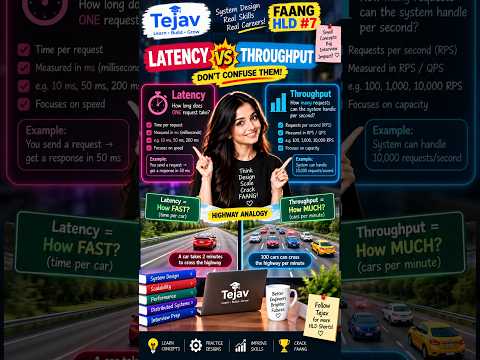
Understanding Latency and Throughput in System Design
Latency is the time for one request, while throughput is how many requests are processed.

⚡ One HLD concept. 60 seconds. Interview ready
Log Replication and Majority Commit in Distributed Systems
Log replication ensures data consistency by requiring majority acknowledgment before committing changes.

⚡ One HLD concept. 60 seconds. Interview ready
Leader Election in Distributed Systems Explained
Leader election helps distributed systems select one coordinator from many nodes.
⚡ One HLD concept. 60 seconds. Interview ready
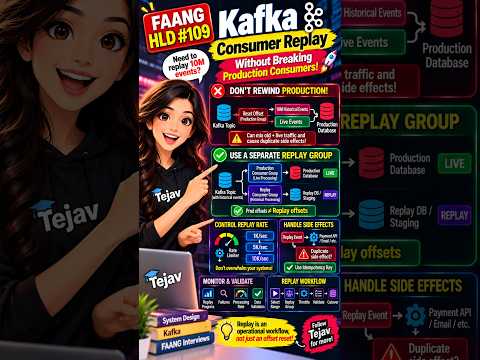
Kafka Replay Without Breaking Production: Safe Architecture
You can replay Kafka events safely by separating live and replay processes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Shards and Replicas in HLD
Elasticsearch uses shards for data distribution and replicas for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.