
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Results · 46 for “Retry Mechanism”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket Rate Limiting Explained for Interviews
The Token Bucket algorithm helps manage how many requests a server can handle.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.

⚡ One HLD concept. 60 seconds. Interview ready
Log Replication and Majority Commit in Distributed Systems
Log replication ensures data consistency by requiring majority acknowledgment before committing changes.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Raft Consensus: Terms, Elections & Log Replication
Raft consensus helps distributed systems elect leaders and replicate logs reliably.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Raft Safety — Why Committed Entries Survive Leader Failure! 🛡️
Raft's safety rules guarantee that committed entries are preserved even after leader failures.

⚡ One HLD concept. 60 seconds. Interview ready
Raft Leader Failure and Re-election Process Explained
Raft handles leader failure by allowing followers to elect a new leader through voting.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retry Topics and Delayed Retries Explained
Kafka uses retry topics and delayed retries to manage message failures efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.
⚡ One HLD concept. 60 seconds. Interview ready
Kafka Producer Reliability: ACKs, Retries & Idempotence
Kafka producers use ACKs, retries, and idempotence to ensure reliable message delivery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Raft Log Replication: matchIndex vs commitIndex
matchIndex tracks what each follower has, while commitIndex shows what is committed.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Safely: Reprocess Messages Without Losing Data
Kafka allows safe message reprocessing by resetting consumer positions without altering data.

⚡ One HLD concept. 60 seconds. Interview ready
Read-After-Write Consistency in Database Systems
Read-after-write consistency ensures users see their latest updates immediately.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.
⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Kafka Seek — Replay Specific Messages Without Replaying Everything! 🎯
Kafka's `seek()` lets you replay only specific messages, saving time.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.
⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding ZooKeeper Ephemeral and Sequential Nodes
ZooKeeper uses ephemeral and sequential nodes for managing distributed services effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Raft vs Paxos — What's the Difference? Consensus Explained! ⚡
Raft and Paxos are protocols that help computers agree on values in distributed systems.

⚡ One HLD concept. 60 seconds. Interview ready
Message Delivery Semantics: At-Most-Once vs At-Least-Once vs Exactly-Once
Message delivery semantics define how messages are sent in distributed systems and handle failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Rebalance: Avoiding Work Loss or Duplication
Kafka rebalance can lead to lost or duplicated work if not handled carefully.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Dead Letter Topics and Poison Messages
Kafka uses Dead Letter Topics to handle messages that repeatedly fail processing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Lamport Timestamps in Distributed Systems
Lamport Timestamps help order events in distributed systems while preserving causality.
⚡ One HLD concept. 60 seconds. Interview ready
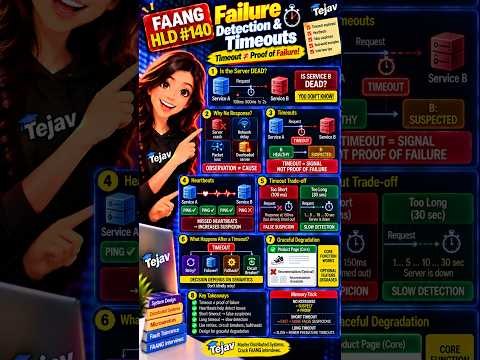
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.