
I'm preparing for
Topic · IT & Coding
distributed systems
60 shorts across 1 course, in learning order
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Results · 15 for “Consumer Lag Management”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Backpressure Strategies: Handling Traffic Spikes
Backpressure helps manage message flow in Kafka during traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Lamport Timestamps in Distributed Systems
Lamport Timestamps help order events in distributed systems while preserving causality.
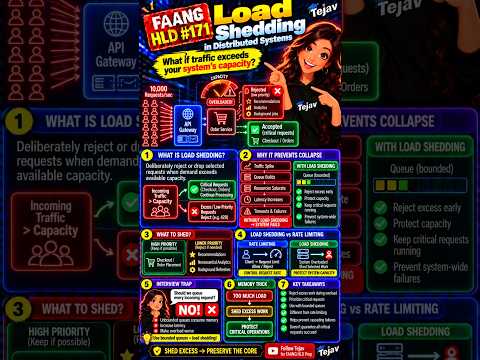
⚡ One HLD concept. 60 seconds. Interview ready
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Vector Clocks in Distributed Systems
Vector clocks help track the order and concurrency of events in distributed systems.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket Rate Limiting Explained for Interviews
The Token Bucket algorithm helps manage how many requests a server can handle.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Distributed Clocks in Systems Design
In distributed systems, timestamps don't always reflect the true order of events.
🧠Related by meaning
Not tagged “distributed systems”, but closely connected


