
I'm preparing for
Topic · IT & Coding
distributed systems
60 shorts across 1 course, in learning order
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Shorts · 60
← Front page
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Node Roles for Scaling Clusters
Elasticsearch has different node roles that help manage data and scale clusters effectively.
⚡ One HLD concept. 60 seconds. Interview ready
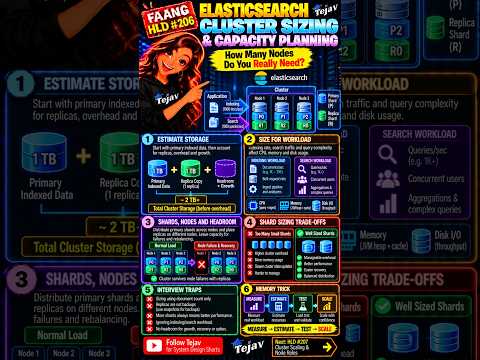
Elasticsearch Cluster Sizing: How Many Nodes Do You Need?
The number of Elasticsearch nodes depends on storage, workload, and performance needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Architecture: How Distributed Search Works
Elasticsearch uses distributed architecture to search data quickly across multiple servers.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Shards vs Replicas: Partitioning vs Duplication
Primary shards partition data, while replica shards duplicate it for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Observability in Distributed Systems: Debugging Production Issues
Observability helps engineers understand system behavior to debug production issues effectively.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.
⚡ One HLD concept. 60 seconds. Interview ready
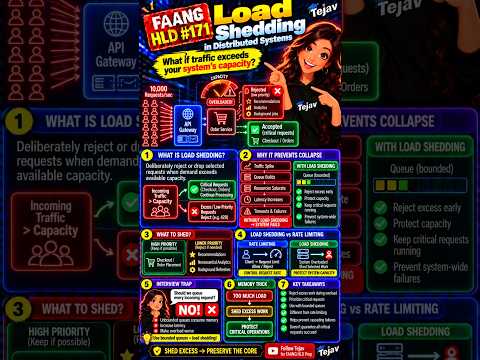
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Circuit Breaker: CLOSED, OPEN, and HALF-OPEN States
The Circuit Breaker pattern controls service calls to prevent failures from spreading.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.
⚡ One HLD concept. 60 seconds. Interview ready
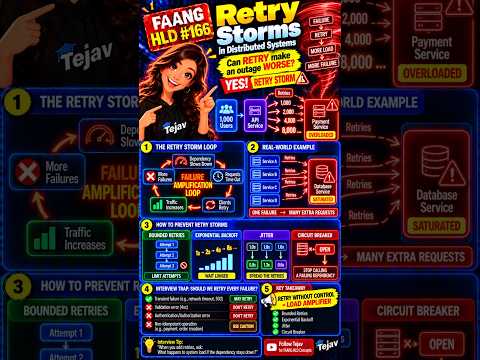
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
When to Use Microservices in Software Design
Microservices are useful when you need independent scaling, deployment, and clear boundaries in software design.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding gRPC Architecture: Behind the Call
gRPC allows efficient communication between services using a structured request-response model.
⚡ One HLD concept. 60 seconds. Interview ready
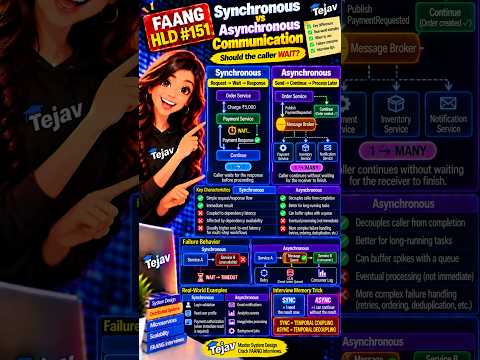
HLD: Synchronous vs Asynchronous Communication Explained
Synchronous communication waits for a response, while asynchronous continues without waiting.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Causality in Distributed Systems
Causality in distributed systems helps understand how events influence each other, beyond just timestamps.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Vector Clocks in Distributed Systems
Vector clocks help track the order and concurrency of events in distributed systems.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Lamport Timestamps in Distributed Systems
Lamport Timestamps help order events in distributed systems while preserving causality.
🧠Related by meaning
Not tagged “distributed systems”, but closely connected


