
I'm preparing for
Topic
distributed systems
21 shorts across 1 course, in learning order
🎛️ Narrow downsubject · level · topic2▾
Results · 8 for “High Availability Systems”
← Front page✨ Smart search: matched by meaning, not just words
⚡ One HLD concept. 60 seconds. Interview ready
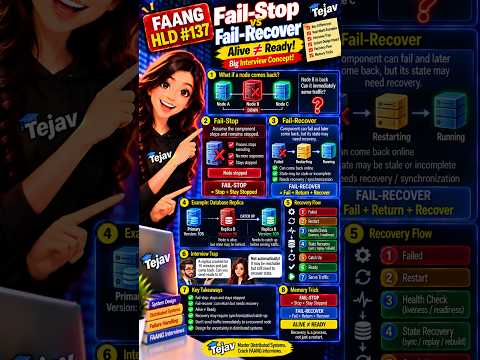
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
Consistent Hashing: Key to Distributed Systems Scalability
Consistent hashing helps distribute data across servers with minimal movement.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Log Replication and Majority Commit in Distributed Systems
Log replication ensures data consistency by requiring majority acknowledgment before committing changes.

⚡ One HLD concept. 60 seconds. Interview ready
Message Delivery Semantics: At-Most-Once vs At-Least-Once vs Exactly-Once
Message delivery semantics define how messages are sent in distributed systems and handle failures.

⚡ One HLD concept. 60 seconds. Interview ready
ZooKeeper Watches: Avoiding the Thundering Herd Problem
ZooKeeper watches notify clients of changes, avoiding constant polling and reducing server load.
⚡ One HLD concept. 60 seconds. Interview ready
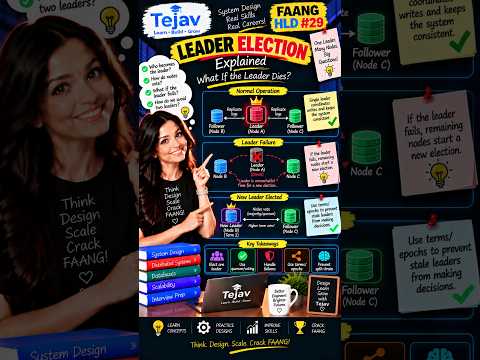
Leader Election in Distributed Systems: Handling Leader Failures
Leader election ensures a single node coordinates tasks in distributed systems, even after failures.
🧠Related by meaning
Not tagged “distributed systems”, but closely connected


