
I'm preparing for
🎛️ Narrow downsubject · level · topic1▾
Results · 14 for “Understanding of event-driven architecture”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Causality in Distributed Systems
Causality in distributed systems helps understand how events influence each other, beyond just timestamps.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding gRPC Architecture: Behind the Call
gRPC allows efficient communication between services using a structured request-response model.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Stateful Stream Processing: How Does It Remember?
Kafka uses state stores to remember previous events in stateful stream processing.
⚡ One HLD concept. 60 seconds. Interview ready
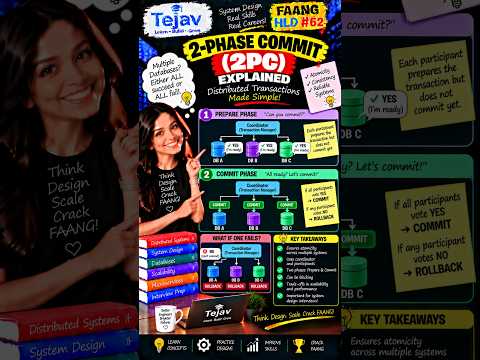
Understanding 2-Phase Commit in Distributed Transactions
2-Phase Commit helps maintain data consistency in transactions across multiple databases.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Async Commit Ordering: Can Older Offsets Overwrite Newer Ones?
Older offsets can overwrite newer ones in Kafka if not handled properly.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Physical vs Logical Time in Distributed Systems
Physical time tells when events happen, while logical time tells their order.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Kafka Backpressure Explained — What Happens When Consumers Can't Keep Up? 🚨
Backpressure prevents system overload by managing message processing rates in Kafka.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.
⚡ One HLD concept. 60 seconds. Interview ready
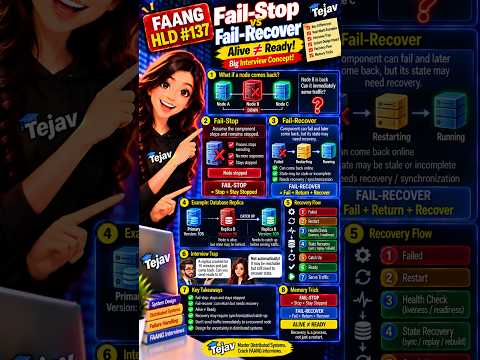
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka commitSync vs commitAsync: Choosing the Right Method
Kafka's commitSync waits for confirmation, while commitAsync continues immediately.

⚡ One HLD concept. 60 seconds. Interview ready
Message Delivery Semantics: At-Most-Once vs At-Least-Once vs Exactly-Once
Message delivery semantics define how messages are sent in distributed systems and handle failures.