
I'm preparing for
🎛️ Narrow downsubject · level · topic2▾
Results · 41 for “Cache strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Eviction Policies: LRU, LFU, and FIFO Explained
Cache eviction policies determine which data to remove when caches are full.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Hits: Reducing Database Load
Caching helps applications respond faster by serving data from memory instead of hitting the database.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CDN: How Cache Hits Improve Performance
A CDN speeds up web applications by caching content closer to users.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Invalidation: TTL vs Freshness Explained
Cache invalidation is about knowing when to refresh cached data.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Penetration in System Design
Cache penetration occurs when requests for non-existent data overload the database.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.
⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
Elasticsearch offers three main autocomplete strategies, each with unique benefits and trade-offs.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Database Indexing: How to Make Queries Fast
Database indexing speeds up data retrieval by allowing quick lookups.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Composite Indexes: Speed Up Multi-Column Queries in Databases
Composite indexes speed up database queries that filter or sort by multiple columns.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM for Cost Management
Elasticsearch ILM automates index management to reduce storage costs and meet data needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Keep-Alive in Networking: Efficient HTTP Connections
Keep-Alive allows reusing HTTP connections to improve efficiency and reduce overhead.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.
⚡ One HLD concept. 60 seconds. Interview ready
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
API Pagination: Efficiently Handling Large Datasets
API pagination helps manage large datasets by breaking them into smaller parts.

⚡ One HLD concept. 60 seconds. Interview ready
Consistent Hashing: Key to Distributed Systems Scalability
Consistent hashing helps distribute data across servers with minimal movement.

⚡ One HLD concept. 60 seconds. Interview ready
Read-After-Write Consistency in Database Systems
Read-after-write consistency ensures users see their latest updates immediately.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Search Engine Architecture and Its Components
Search engines collect, index, retrieve, and rank documents to provide relevant results.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM: Hot, Warm, Cold Phases
Elasticsearch ILM automates data management through defined lifecycle phases.
⚡ One HLD concept. 60 seconds. Interview ready
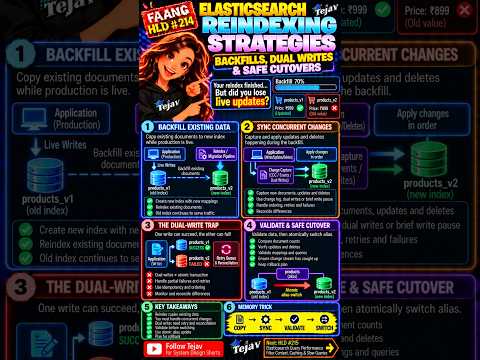
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Full-Text Search vs Database Search with Elasticsearch
Choose Elasticsearch for complex text searches, but use databases for structured queries.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Async Commit Ordering: Can Older Offsets Overwrite Newer Ones?
Older offsets can overwrite newer ones in Kafka if not handled properly.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.