
I'm preparing for
🎛️ Narrow downsubject · level · topic2▾
Results · 31 for “Backup strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Disaster Recovery Across Regions: Can Your System Recover?
Disaster recovery ensures systems can restore services and data after major disruptions.

⚡ One HLD concept. 60 seconds. Interview ready
Active-Passive Architecture: Handling Production Downtime
Active-passive architecture ensures a standby system takes over if the main system fails.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Point-in-Time Recovery: Recovering Deleted Database Data
Point-in-Time Recovery allows databases to be restored to a specific moment before data loss.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.

⚡ One HLD concept. 60 seconds. Interview ready
Disaster Recovery Testing: Ensuring Your DR Plan Works
Disaster Recovery Testing verifies that your recovery plan works effectively in real situations.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding High Availability in System Design
High Availability ensures your application remains operational even during server failures.
⚡ One HLD concept. 60 seconds. Interview ready
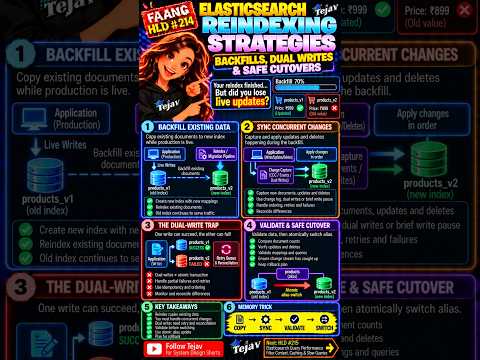
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Sync vs Async Replication: Choosing the Right Approach
Synchronous replication waits for confirmation from replicas, while asynchronous allows faster writes without waiting.
⚡ One HLD concept. 60 seconds. Interview ready
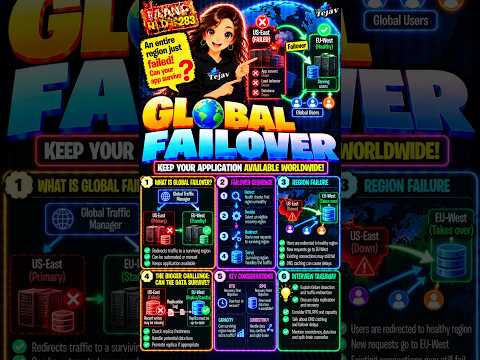
Global Failover: What Happens When an Entire Region Goes Down?
Global failover ensures applications remain available by redirecting traffic from failed regions to functioning ones.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Backpressure Strategies: Handling Traffic Spikes
Backpressure helps manage message flow in Kafka during traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding SPOF: Why Your App Can Go Down with Healthy Servers
A single component's failure can take down your entire application, even with redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Late-Arriving Events - Drop, Update, or Replay?
Late-arriving events can be dropped, updated, or routed based on system needs.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Safely: Reprocess Messages Without Losing Data
Kafka allows safe message reprocessing by resetting consumer positions without altering data.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.
⚡ One HLD concept. 60 seconds. Interview ready
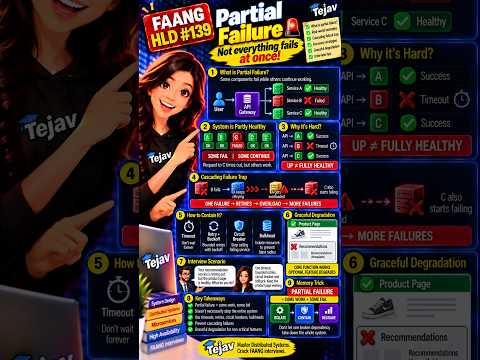
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.