
I'm preparing for
🎛️ Narrow downsubject · level · topic2▾
Results · 35 for “High Availability Systems”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Availability vs Reliability in System Design
Availability is about access; reliability is about correct performance.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Load Balancers in System Design
Load balancers distribute traffic across multiple servers to enhance performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Message Queues in Distributed Systems
Message queues allow services to communicate asynchronously, improving scalability and reliability.
⚡ One HLD concept. 60 seconds. Interview ready
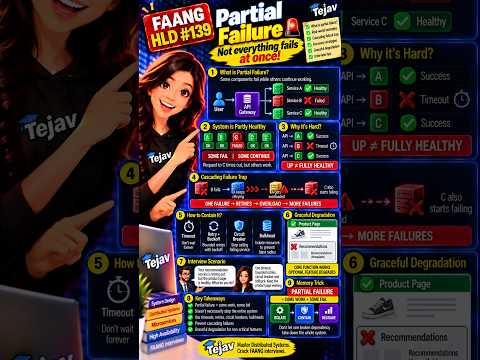
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.
⚡ One HLD concept. 60 seconds. Interview ready
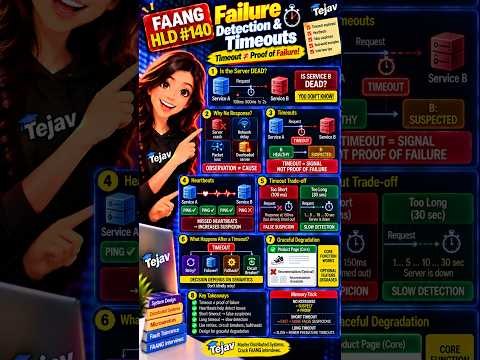
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Scalable System Design in FAANG Companies
FAANG engineers use high-level design principles to create scalable systems.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.

⚡ One HLD concept. 60 seconds. Interview ready
Sync vs Async Replication: Choosing the Right Approach
Synchronous replication waits for confirmation from replicas, while asynchronous allows faster writes without waiting.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Vertical and Horizontal Scaling in System Design
Vertical scaling means upgrading one server, while horizontal scaling means adding more servers.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.
⚡ One HLD concept. 60 seconds. Interview ready
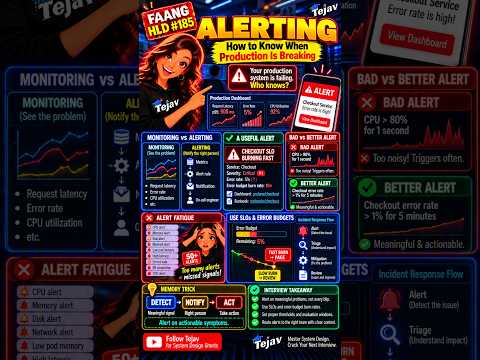
Understanding Alerting in High-Level Design
Alerting helps notify the right people about production issues quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.
⚡ One HLD concept. 60 seconds. Interview ready
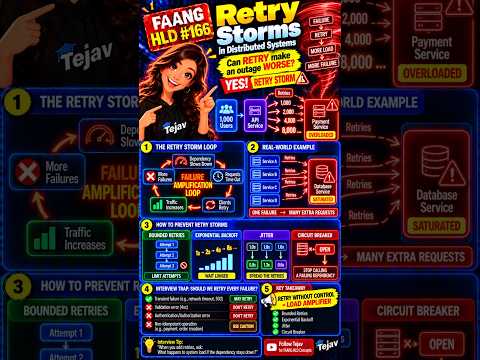
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Shards and Replicas in HLD
Elasticsearch uses shards for data distribution and replicas for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.