
I'm preparing for
🎛️ Narrow downsubject · level · topic2▾
Results · 26 for “Performance Tuning in MongoDB”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Rescoring: Improve Search Result Rankings
Elasticsearch rescoring improves search result rankings using a two-stage process.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Execution: How Searches Work Across Shards
Elasticsearch distributes search queries across shards to find and retrieve results quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Fetch & Batching: Boosting Throughput
Kafka consumers can fetch data in batches to improve throughput and reduce latency.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Lag Monitoring: Prevent Production Issues
Monitoring Kafka consumer lag helps prevent production problems by ensuring consumers keep up with message traffic.
⚡ One HLD concept. 60 seconds. Interview ready
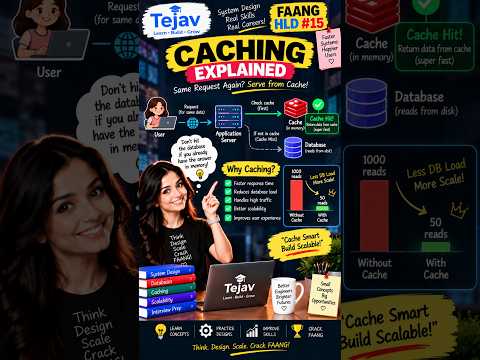
Understanding Cache Hits: Reducing Database Load
Caching helps applications respond faster by serving data from memory instead of hitting the database.
⚡ One HLD concept. 60 seconds. Interview ready
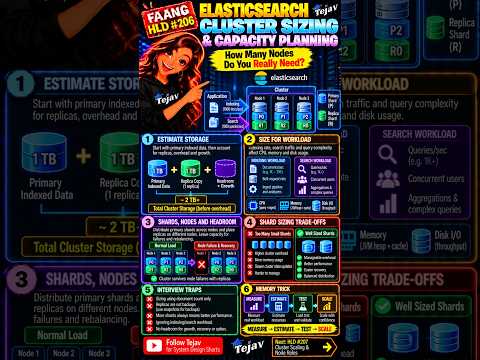
Elasticsearch Cluster Sizing: How Many Nodes Do You Need?
The number of Elasticsearch nodes depends on storage, workload, and performance needs.

⚡ One HLD concept. 60 seconds. Interview ready
API Pagination: Efficiently Handling Large Datasets
API pagination helps manage large datasets by breaking them into smaller parts.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Shards and Replicas in HLD
Elasticsearch uses shards for data distribution and replicas for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Multithreading: Processing Messages in Parallel
Kafka consumers can use multiple threads to speed up message processing, but it complicates ordering and offset management.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Architecture: How Distributed Search Works
Elasticsearch uses distributed architecture to search data quickly across multiple servers.
⚡ One HLD concept. 60 seconds. Interview ready
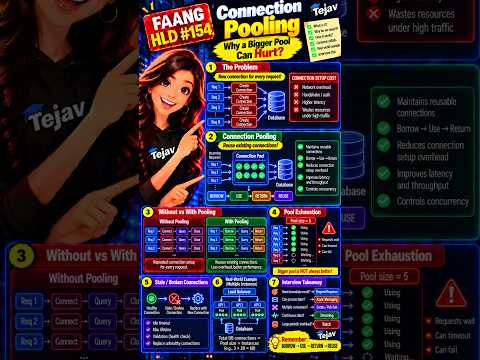
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Backpressure Strategies: Handling Traffic Spikes
Backpressure helps manage message flow in Kafka during traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Node Roles for Scaling Clusters
Elasticsearch has different node roles that help manage data and scale clusters effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Shards vs Replicas: Partitioning vs Duplication
Primary shards partition data, while replica shards duplicate it for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Full-Text Search vs Database Search with Elasticsearch
Choose Elasticsearch for complex text searches, but use databases for structured queries.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Refresh: Why Your Document Isn’t Searchable Yet
A document in Elasticsearch isn't searchable right after it's saved due to the refresh process.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.