
I'm preparing for
🎛️ Narrow downsubject · level · topic2▾
Results · 23 for “Timeout Strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.
⚡ One HLD concept. 60 seconds. Interview ready
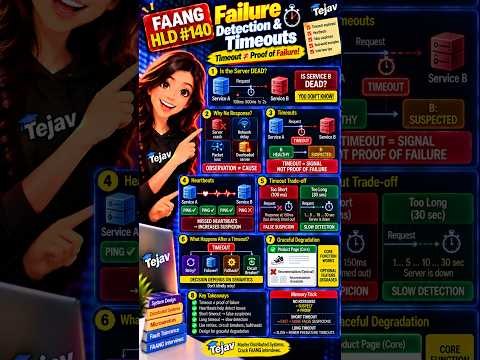
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Invalidation: TTL vs Freshness Explained
Cache invalidation is about knowing when to refresh cached data.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.
⚡ One HLD concept. 60 seconds. Interview ready
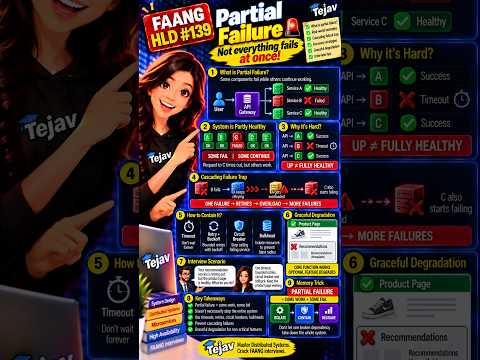
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.
⚡ One HLD concept. 60 seconds. Interview ready
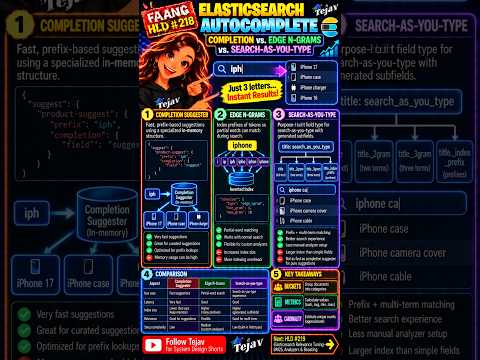
Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
Elasticsearch offers three main autocomplete strategies, each with unique benefits and trade-offs.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Backpressure Strategies: Handling Traffic Spikes
Backpressure helps manage message flow in Kafka during traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Data Streams vs. Time-Based Indices: Which to Choose?
Elasticsearch offers Data Streams for simplicity and Time-Based Indices for control in managing time-series data.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.
⚡ One HLD concept. 60 seconds. Interview ready
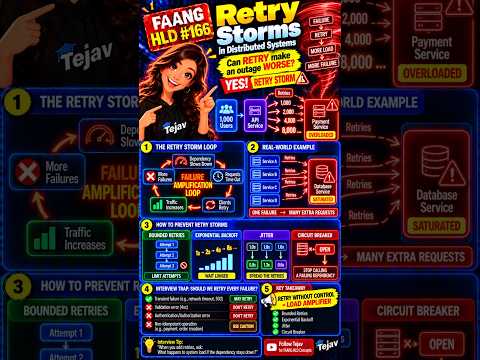
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket Rate Limiting Explained for Interviews
The Token Bucket algorithm helps manage how many requests a server can handle.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.
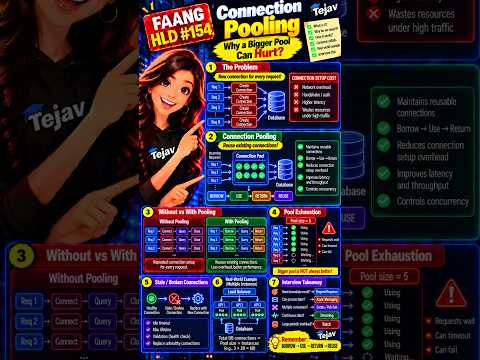
⚡ One HLD concept. 60 seconds. Interview ready
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.