
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 24 for “Data aggregation fundamentals”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Metrics vs Buckets Explained
Elasticsearch aggregations help summarize data using metrics for calculations and buckets for grouping.

⚡ One HLD concept. 60 seconds. Interview ready
API Pagination: Efficiently Handling Large Datasets
API pagination helps manage large datasets by breaking them into smaller parts.
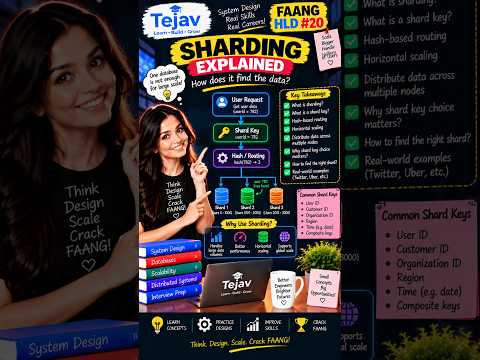
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Data Streams vs. Time-Based Indices: Which to Choose?
Elasticsearch offers Data Streams for simplicity and Time-Based Indices for control in managing time-series data.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Data Streams in HLD
Elasticsearch Data Streams simplify time-series data management with one name for many indices.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Stateful Stream Processing: How Does It Remember?
Kafka uses state stores to remember previous events in stateful stream processing.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Quorum Reads in Distributed Systems
Quorum Reads ensure data consistency by querying multiple replicas in distributed systems.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Fetch Limits vs Poll Records: Understanding the Difference
Fetch limits control data size from Kafka, while poll records limit processed records.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Transactions and ACID Properties in Databases
Transactions ensure database operations are reliable using ACID properties.

⚡ One HLD concept. 60 seconds. Interview ready
SQL vs NoSQL: Choosing the Right Database for Your Needs
The choice between SQL and NoSQL databases depends on your application's specific needs.

⚡ One HLD concept. 60 seconds. Interview ready
Observability in Distributed Systems: Debugging Production Issues
Observability helps engineers understand system behavior to debug production issues effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.
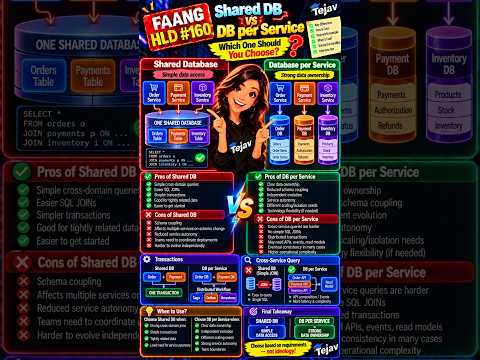
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Shared DB vs Database per Service Trade-Offs
Choosing between a shared database and a database per service affects system design significantly.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Streams Windowing: Tumbling vs Hopping Windows Explained
Kafka Streams uses tumbling and hopping windows for time-based data aggregation.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Fetch & Batching: Boosting Throughput
Kafka consumers can fetch data in batches to improve throughput and reduce latency.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Streams vs Consumer: Choosing the Right Tool
Kafka Streams offers higher-level abstractions, while Kafka Consumer provides direct control.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.