
I'm preparing for
Topic
system design
116 shorts across 1 course, in learning order
🎛️ Narrow downsubject · level · topic1▾
Results · 29 for “Elasticsearch Performance Tuning”
← Front page✨ Smart search: matched by meaning, not just words
⚡ One HLD concept. 60 seconds. Interview ready
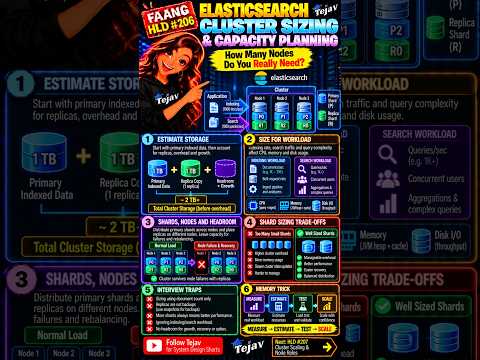
Elasticsearch Cluster Sizing: How Many Nodes Do You Need?
The number of Elasticsearch nodes depends on storage, workload, and performance needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Execution: How Searches Work Across Shards
Elasticsearch distributes search queries across shards to find and retrieve results quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Shards and Replicas in HLD
Elasticsearch uses shards for data distribution and replicas for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Refresh: Why Your Document Isn’t Searchable Yet
A document in Elasticsearch isn't searchable right after it's saved due to the refresh process.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM for Cost Management
Elasticsearch ILM automates index management to reduce storage costs and meet data needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Filters vs Queries: MUST vs FILTER Explained
Filters check conditions without affecting relevance, while queries do.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Index Templates and Components
Elasticsearch index templates automatically apply settings to new indices based on patterns.
⚡ One HLD concept. 60 seconds. Interview ready
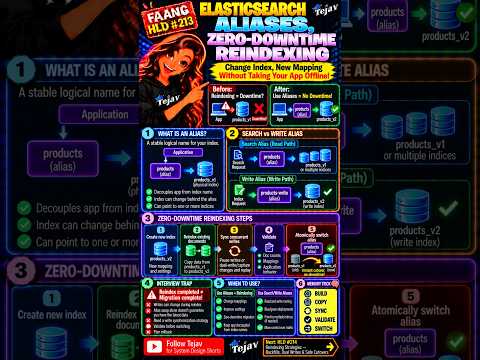
Elasticsearch Zero-Downtime Reindexing: The Alias Switch Trick
You can update Elasticsearch indices without downtime using alias switching.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Fuzzy Search: Handling Typos in Queries
Elasticsearch fuzzy search allows finding results even with typos in queries.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Full-Text Search vs Database Search with Elasticsearch
Choose Elasticsearch for complex text searches, but use databases for structured queries.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aliases and Rollover: Zero-Downtime Index Switching
Elasticsearch aliases allow zero-downtime switching between indices for applications.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM: Hot, Warm, Cold Phases
Elasticsearch ILM automates data management through defined lifecycle phases.
⚡ One HLD concept. 60 seconds. Interview ready
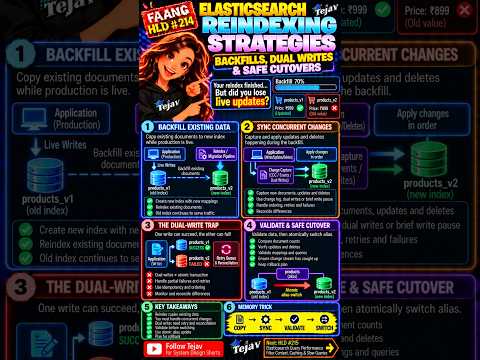
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Data Streams in HLD
Elasticsearch Data Streams simplify time-series data management with one name for many indices.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Mapping: Dynamic vs Explicit Explained
Elasticsearch mapping defines how fields are indexed and searched, with dynamic and explicit options.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Data Streams vs. Time-Based Indices: Which to Choose?
Elasticsearch offers Data Streams for simplicity and Time-Based Indices for control in managing time-series data.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Fetch Limits vs Poll Records: Understanding the Difference
Fetch limits control data size from Kafka, while poll records limit processed records.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.
⚡ One HLD concept. 60 seconds. Interview ready
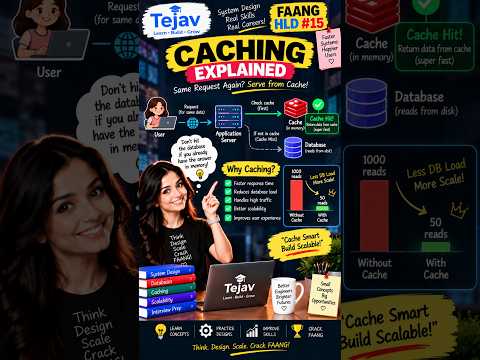
Understanding Cache Hits: Reducing Database Load
Caching helps applications respond faster by serving data from memory instead of hitting the database.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.
⚡ One HLD concept. 60 seconds. Interview ready
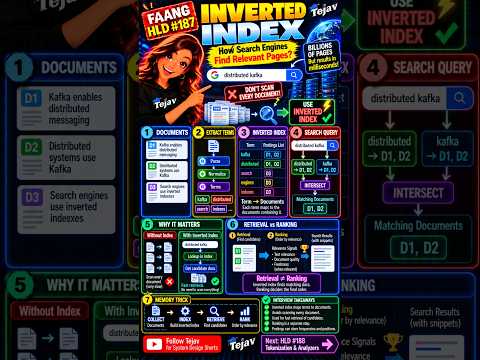
Inverted Index: How Search Engines Find Pages Efficiently
An inverted index helps search engines quickly find documents containing specific terms.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Search Engine Architecture and Its Components
Search engines collect, index, retrieve, and rank documents to provide relevant results.
⚡ One HLD concept. 60 seconds. Interview ready
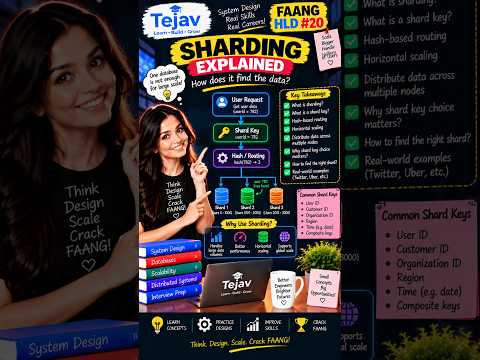
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.
🧠Related by meaning
Not tagged “system design”, but closely connected

