
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 39 for “Error handling principles”
← Front page✨ Smart search: matched by meaning, not just words
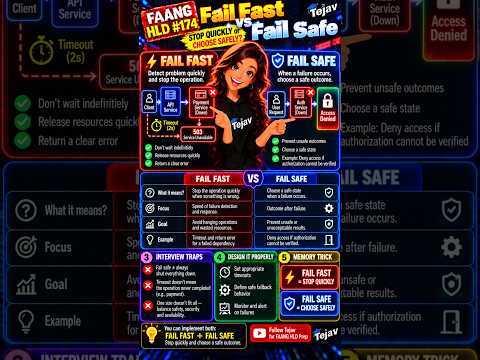
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fail Fast vs Fail Safe in System Design
Fail Fast means stopping quickly on errors, while Fail Safe ensures safety in failures.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.
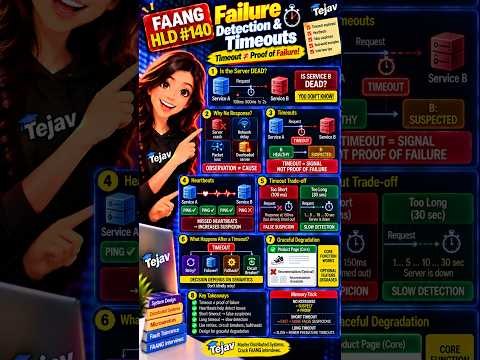
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.
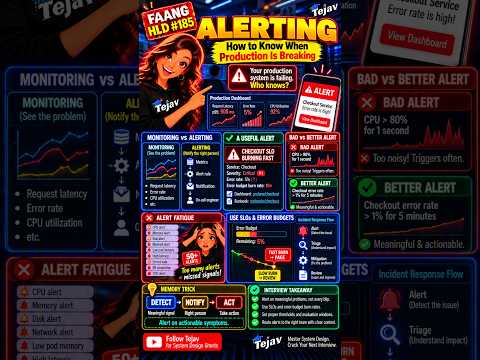
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Alerting in High-Level Design
Alerting helps notify the right people about production issues quickly.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.
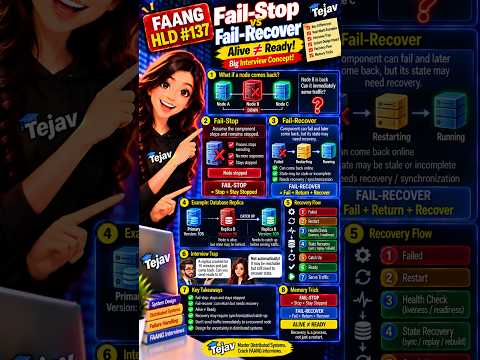
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.
⚡ One HLD concept. 60 seconds. Interview ready
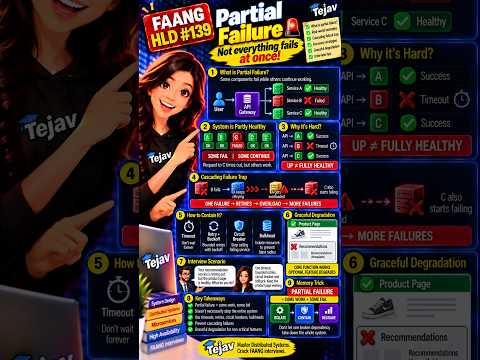
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
REST API Design: Building Scalable APIs for Real-World Use
REST API design focuses on creating clean, efficient, and scalable web services.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Circuit Breaker: CLOSED, OPEN, and HALF-OPEN States
The Circuit Breaker pattern controls service calls to prevent failures from spreading.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Error Budgets in High-Level Design
An error budget shows how much downtime is acceptable while meeting reliability goals.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Availability vs Reliability in System Design
Availability is about access; reliability is about correct performance.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Dead Letter Topics and Poison Messages
Kafka uses Dead Letter Topics to handle messages that repeatedly fail processing.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retry Topics and Delayed Retries Explained
Kafka uses retry topics and delayed retries to manage message failures efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Protobuf and Schema Evolution: Avoid Breaking Changes
Protobuf schema evolution requires careful changes to avoid breaking existing clients.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Write-Ahead Log (WAL) in Databases
Write-Ahead Log ensures data is safely recorded before changes are made.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: 5 Microservices Communication Patterns Explained
Microservices can communicate using five key patterns based on their needs.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
What FAANG Interviewers Evaluate in System Design Interviews
FAANG interviewers evaluate problem understanding, architecture, scalability, and communication skills.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Functional and Non-Functional Requirements
Functional requirements define what a system does, while non-functional requirements define how it performs.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.
⚡ One HLD concept. 60 seconds. Interview ready
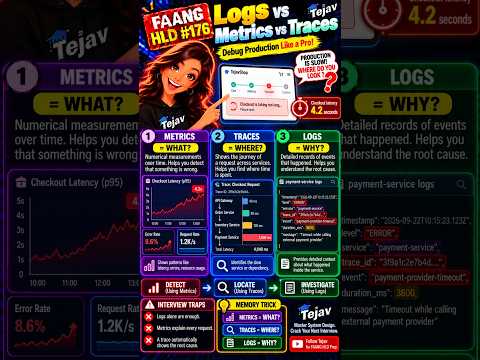
Understanding Logs, Metrics, and Traces in Software Engineering
Logs, metrics, and traces help engineers debug issues in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Idempotency in System Design
Idempotency ensures that repeated operations in APIs do not cause duplicate effects.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Graceful Shutdown: Stop Without Losing Work
Graceful shutdown in Kafka ensures no data loss during consumer termination.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.