
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 26 for “Incident Response Strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Disaster Recovery Across Regions: Can Your System Recover?
Disaster recovery ensures systems can restore services and data after major disruptions.
⚡ One HLD concept. 60 seconds. Interview ready
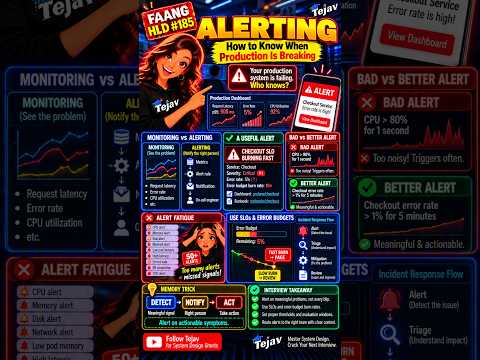
Understanding Alerting in High-Level Design
Alerting helps notify the right people about production issues quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding SSRF: Server-Side Request Forgery Explained
SSRF is a vulnerability where an attacker tricks a server into making unintended requests.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the RED Method for Microservices Monitoring
The RED Method helps monitor microservices using Rate, Errors, and Duration metrics.

⚡ One HLD concept. 60 seconds. Interview ready
Disaster Recovery Testing: Ensuring Your DR Plan Works
Disaster Recovery Testing verifies that your recovery plan works effectively in real situations.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Understanding Request-Response vs Events in System Design
Request-Response asks for a result, while Events notify that something has happened.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPO and RTO in Disaster Recovery
RPO and RTO are key metrics for planning disaster recovery strategies.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Active-Passive Architecture: Handling Production Downtime
Active-passive architecture ensures a standby system takes over if the main system fails.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Single Region vs Multi-Region Architecture
Choosing between single and multi-region architecture affects system resilience and cost.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CSRF: Protecting Against Unwanted Requests
CSRF tricks your browser into making requests without your consent.
⚡ One HLD concept. 60 seconds. Interview ready
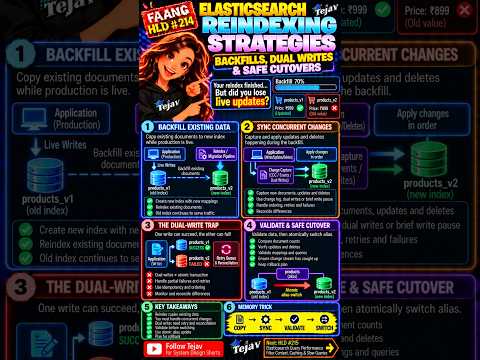
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.
⚡ One HLD concept. 60 seconds. Interview ready
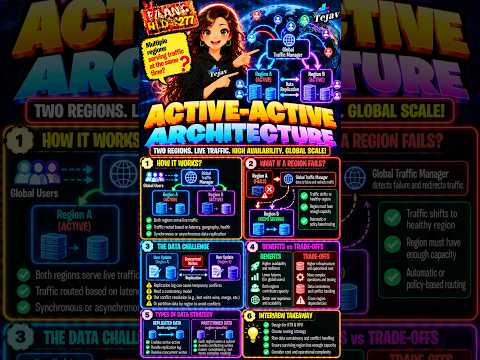
Understanding Active-Active Architecture in Distributed Systems
Active-Active Architecture uses multiple regions to serve traffic simultaneously for better resilience.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Late-Arriving Events - Drop, Update, or Replay?
Late-arriving events can be dropped, updated, or routed based on system needs.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.
⚡ One HLD concept. 60 seconds. Interview ready
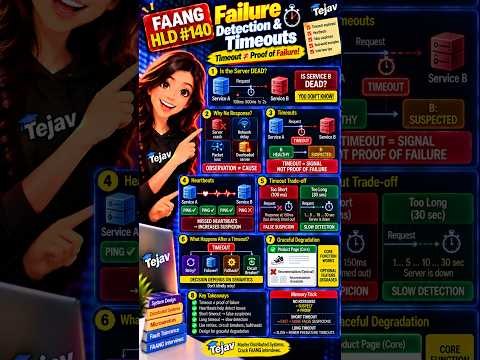
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Point-in-Time Recovery: Recovering Deleted Database Data
Point-in-Time Recovery allows databases to be restored to a specific moment before data loss.
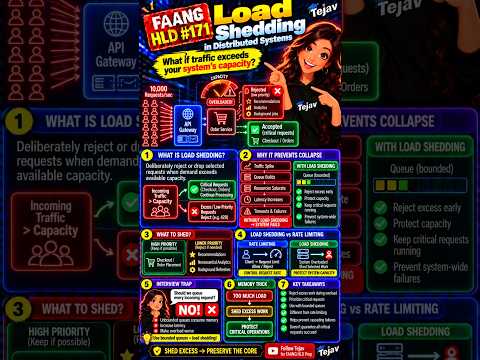
⚡ One HLD concept. 60 seconds. Interview ready
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.