
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 60 for “Index management principles”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM for Cost Management
Elasticsearch ILM automates index management to reduce storage costs and meet data needs.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Index Templates and Components
Elasticsearch index templates automatically apply settings to new indices based on patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Data Streams vs. Time-Based Indices: Which to Choose?
Elasticsearch offers Data Streams for simplicity and Time-Based Indices for control in managing time-series data.

⚡ One HLD concept. 60 seconds. Interview ready
Database Indexing: How to Make Queries Fast
Database indexing speeds up data retrieval by allowing quick lookups.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM: Hot, Warm, Cold Phases
Elasticsearch ILM automates data management through defined lifecycle phases.
⚡ One HLD concept. 60 seconds. Interview ready
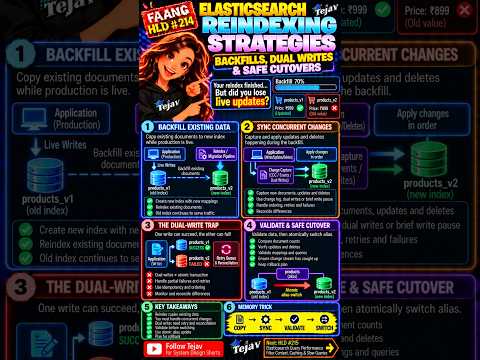
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.
⚡ One HLD concept. 60 seconds. Interview ready
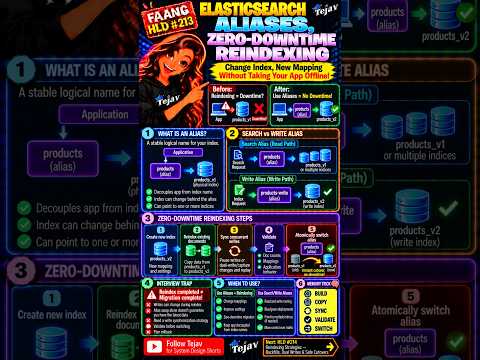
Elasticsearch Zero-Downtime Reindexing: The Alias Switch Trick
You can update Elasticsearch indices without downtime using alias switching.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Raft Log Replication: matchIndex vs commitIndex
matchIndex tracks what each follower has, while commitIndex shows what is committed.

⚡ One HLD concept. 60 seconds. Interview ready
Composite Indexes: Speed Up Multi-Column Queries in Databases
Composite indexes speed up database queries that filter or sort by multiple columns.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aliases and Rollover: Zero-Downtime Index Switching
Elasticsearch aliases allow zero-downtime switching between indices for applications.
⚡ One HLD concept. 60 seconds. Interview ready
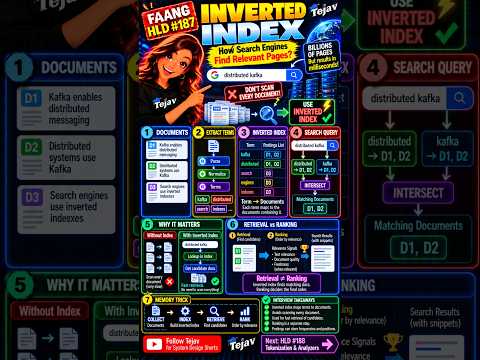
Inverted Index: How Search Engines Find Pages Efficiently
An inverted index helps search engines quickly find documents containing specific terms.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Architecture: How Distributed Search Works
Elasticsearch uses distributed architecture to search data quickly across multiple servers.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Shards and Replicas in HLD
Elasticsearch uses shards for data distribution and replicas for redundancy.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Split Brain: Master Election and Quorum Explained
Elasticsearch uses master election and quorum to prevent split brain scenarios.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Async Commit Ordering: Can Older Offsets Overwrite Newer Ones?
Older offsets can overwrite newer ones in Kafka if not handled properly.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Indexing: Why Can't You Search Your Document Yet?
Elasticsearch documents aren't searchable immediately due to the indexing process.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.
⚡ One HLD concept. 60 seconds. Interview ready
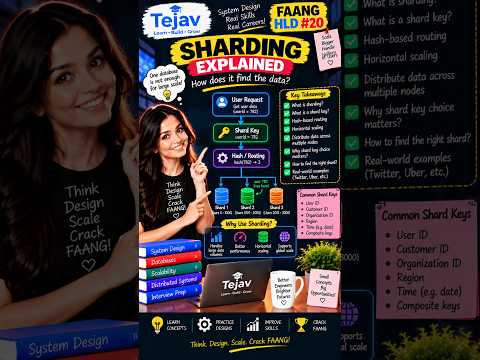
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Search Engine Architecture and Its Components
Search engines collect, index, retrieve, and rank documents to provide relevant results.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Offsets: Auto Commit vs Manual Commit
Kafka consumer offsets help track message processing to avoid loss and duplication.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Full-Text Search vs Database Search with Elasticsearch
Choose Elasticsearch for complex text searches, but use databases for structured queries.
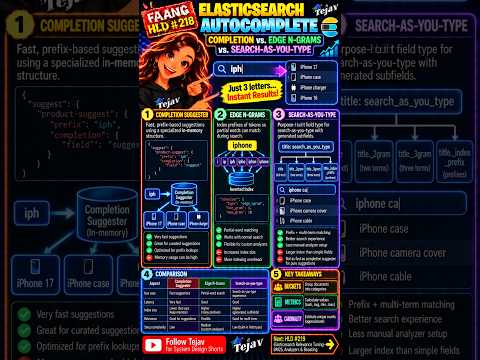
⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
Elasticsearch offers three main autocomplete strategies, each with unique benefits and trade-offs.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Execution: How Searches Work Across Shards
Elasticsearch distributes search queries across shards to find and retrieve results quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Data Streams in HLD
Elasticsearch Data Streams simplify time-series data management with one name for many indices.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Partition Pruning Explained — Scan Less, Query Faster! ⚡
Partition pruning helps databases skip unnecessary data scans, speeding up queries.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Refresh: Why Your Document Isn’t Searchable Yet
A document in Elasticsearch isn't searchable right after it's saved due to the refresh process.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Metrics vs Buckets Explained
Elasticsearch aggregations help summarize data using metrics for calculations and buckets for grouping.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Transactions and ACID Properties in Databases
Transactions ensure database operations are reliable using ACID properties.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
REST API Design: Building Scalable APIs for Real-World Use
REST API design focuses on creating clean, efficient, and scalable web services.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Node Roles for Scaling Clusters
Elasticsearch has different node roles that help manage data and scale clusters effectively.

⚡ One HLD concept. 60 seconds. Interview ready
When to Use Microservices in Software Design
Microservices are useful when you need independent scaling, deployment, and clear boundaries in software design.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Eviction Policies: LRU, LFU, and FIFO Explained
Cache eviction policies determine which data to remove when caches are full.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Relevance Scoring with BM25
Elasticsearch ranks search results using BM25 based on relevance scoring.

⚡ One HLD concept. 60 seconds. Interview ready
API Pagination: Efficiently Handling Large Datasets
API pagination helps manage large datasets by breaking them into smaller parts.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.
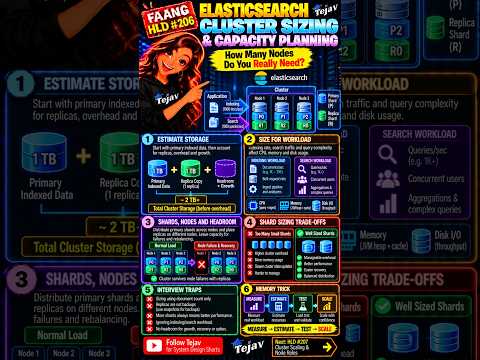
⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Cluster Sizing: How Many Nodes Do You Need?
The number of Elasticsearch nodes depends on storage, workload, and performance needs.

⚡ One HLD concept. 60 seconds. Interview ready
SQL vs NoSQL: Choosing the Right Database for Your Needs
The choice between SQL and NoSQL databases depends on your application's specific needs.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing Service Boundaries in Microservices Architecture
Choosing the right boundaries for microservices is crucial for effective architecture.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding ZooKeeper Ephemeral and Sequential Nodes
ZooKeeper uses ephemeral and sequential nodes for managing distributed services effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Ordering and Keys: Ensuring Message Order
Kafka maintains message order within partitions using keys for routing.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka subscribe() vs assign(): Who Controls Partition Assignment?
Kafka's subscribe() lets the group manage partitions, while assign() gives control to the application.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Isolation Levels in Software Engineering
Database isolation levels determine how transactions interact and affect data consistency.