
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 25 for “Retry Pattern”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.
⚡ One HLD concept. 60 seconds. Interview ready
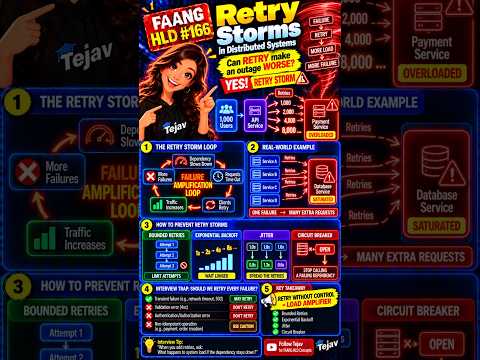
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Circuit Breaker: CLOSED, OPEN, and HALF-OPEN States
The Circuit Breaker pattern controls service calls to prevent failures from spreading.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.
⚡ One HLD concept. 60 seconds. Interview ready
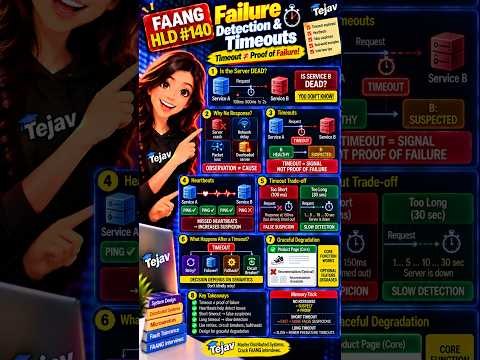
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.
⚡ One HLD concept. 60 seconds. Interview ready
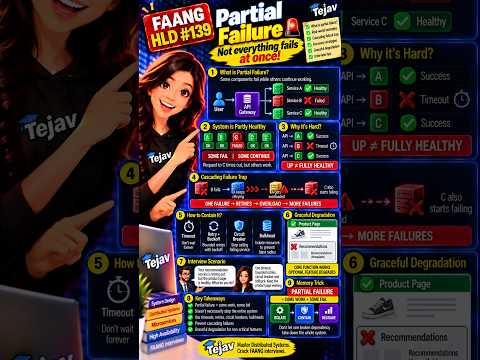
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Pause & Resume: Managing Backpressure Smartly
Kafka consumers can pause and resume message processing to handle backpressure effectively.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Unary vs Streaming RPC in gRPC
gRPC supports four communication patterns: Unary, Server Streaming, Client Streaming, and Bidirectional Streaming.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.
⚡ One HLD concept. 60 seconds. Interview ready
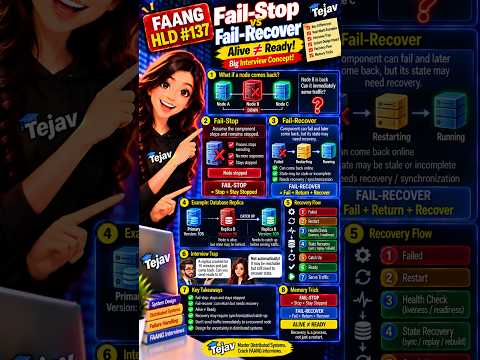
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retry Topics and Delayed Retries Explained
Kafka uses retry topics and delayed retries to manage message failures efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Saga Pattern in Distributed Transactions
The Saga Pattern manages distributed transactions using local transactions and compensating actions.