
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 31 for “Scaling Strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Vertical and Horizontal Scaling in System Design
Vertical scaling means upgrading one server, while horizontal scaling means adding more servers.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.
⚡ One HLD concept. 60 seconds. Interview ready
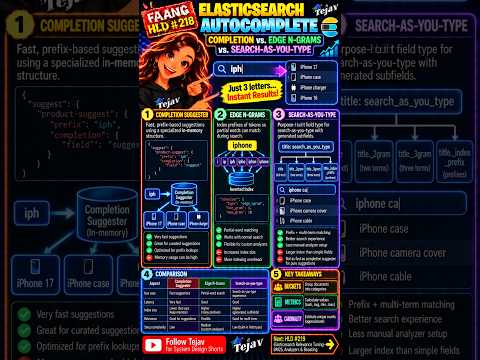
Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
Elasticsearch offers three main autocomplete strategies, each with unique benefits and trade-offs.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Scalable System Design in FAANG Companies
FAANG engineers use high-level design principles to create scalable systems.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding SLIs, SLOs, and SLAs in Reliability Engineering
SLIs measure service performance, SLOs set reliability targets, and SLAs are customer agreements.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.
⚡ One HLD concept. 60 seconds. Interview ready
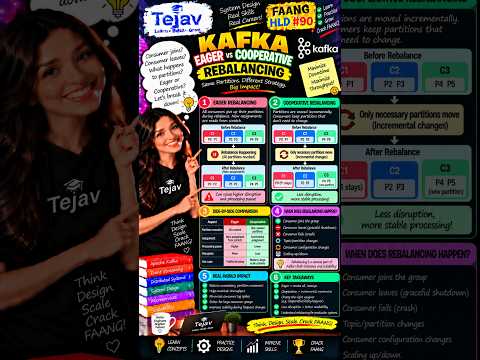
Kafka Eager vs Cooperative Rebalancing: Key Differences
Eager rebalancing revokes all assignments, while cooperative allows incremental changes.

⚡ One HLD concept. 60 seconds. Interview ready
When to Use Microservices in Software Design
Microservices are useful when you need independent scaling, deployment, and clear boundaries in software design.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Eviction Policies: LRU, LFU, and FIFO Explained
Cache eviction policies determine which data to remove when caches are full.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.
⚡ One HLD concept. 60 seconds. Interview ready
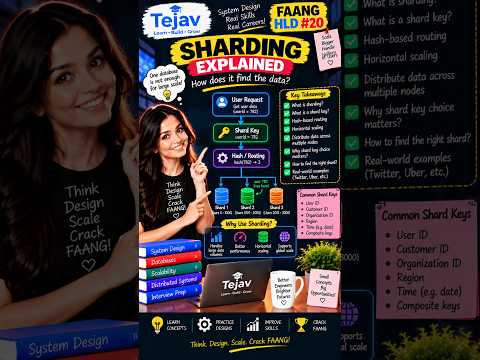
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Mapping: Dynamic vs Explicit Explained
Elasticsearch mapping defines how fields are indexed and searched, with dynamic and explicit options.
⚡ One HLD concept. 60 seconds. Interview ready
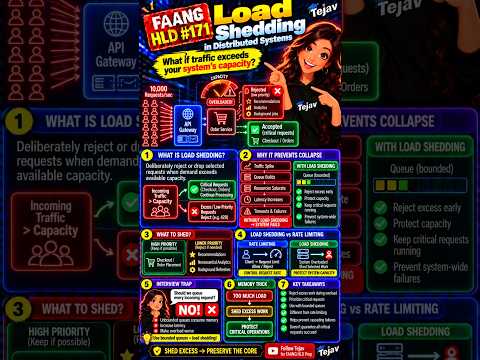
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: 5 Microservices Communication Patterns Explained
Microservices can communicate using five key patterns based on their needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.
⚡ One HLD concept. 60 seconds. Interview ready
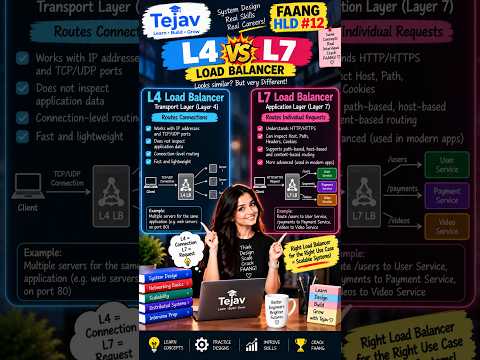
L4 vs L7 Load Balancers: Key Differences Explained
L4 and L7 load balancers differ in how they route network traffic based on layers of the OSI model.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch ILM for Cost Management
Elasticsearch ILM automates index management to reduce storage costs and meet data needs.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Index Templates and Components
Elasticsearch index templates automatically apply settings to new indices based on patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing Service Boundaries in Microservices Architecture
Choosing the right boundaries for microservices is crucial for effective architecture.