
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 21 for “Understanding of Uptime”
← Front page✨ Smart search: matched by meaning, not just words
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Availability vs Reliability in System Design
Availability is about access; reliability is about correct performance.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Error Budgets in High-Level Design
An error budget shows how much downtime is acceptable while meeting reliability goals.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Latency and Throughput in System Design
Latency is the time for one request, while throughput is how many requests are processed.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Lamport Timestamps in Distributed Systems
Lamport Timestamps help order events in distributed systems while preserving causality.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Distributed Clocks in Systems Design
In distributed systems, timestamps don't always reflect the true order of events.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Latency, Throughput, and Response Time
Latency, throughput, and response time are key metrics in system performance.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Physical vs Logical Time in Distributed Systems
Physical time tells when events happen, while logical time tells their order.
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Logs, Metrics, and Traces in Software Engineering
Logs, metrics, and traces help engineers debug issues in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding SLIs, SLOs, and SLAs in Reliability Engineering
SLIs measure service performance, SLOs set reliability targets, and SLAs are customer agreements.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Observability in Distributed Systems: Debugging Production Issues
Observability helps engineers understand system behavior to debug production issues effectively.
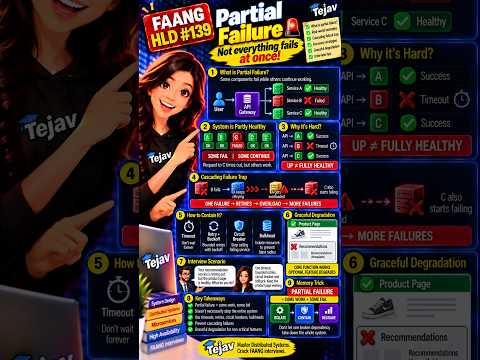
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the RED Method for Microservices Monitoring
The RED Method helps monitor microservices using Rate, Errors, and Duration metrics.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.