
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 42 for “Disaster Recovery Strategies”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Crash Recovery: Resuming Processing Explained
Kafka consumers resume processing from the last committed offset after a crash.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.
⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Without Breaking Production: Safe Architecture
You can replay Kafka events safely by separating live and replay processes.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Lag Recovery Time: How Fast Can Consumers Catch Up?
Kafka lag recovery time is how fast consumers can process backlogged messages.
⚡ One HLD concept. 60 seconds. Interview ready
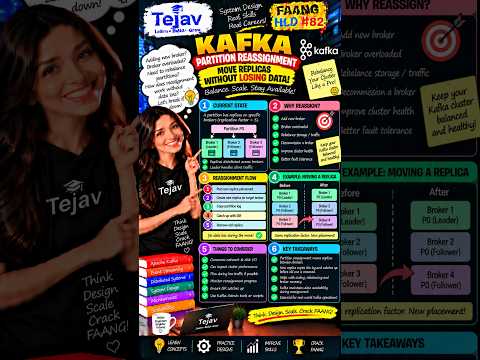
Kafka Partition Reassignment: Move Replicas Without Data Loss
Kafka Partition Reassignment moves replicas between brokers while keeping data safe.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Write-Ahead Log (WAL) in Databases
Write-Ahead Log ensures data is safely recorded before changes are made.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.
⚡ One HLD concept. 60 seconds. Interview ready
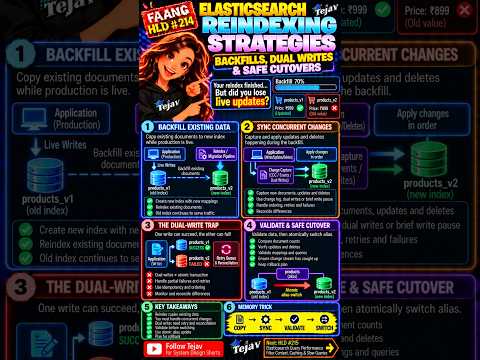
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Safely: Reprocess Messages Without Losing Data
Kafka allows safe message reprocessing by resetting consumer positions without altering data.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retry Topics and Delayed Retries Explained
Kafka uses retry topics and delayed retries to manage message failures efficiently.
⚡ One HLD concept. 60 seconds. Interview ready
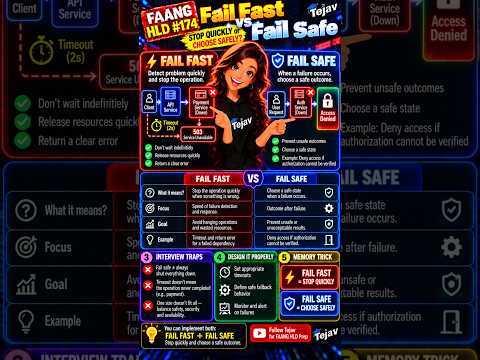
HLD: Fail Fast vs Fail Safe in System Design
Fail Fast means stopping quickly on errors, while Fail Safe ensures safety in failures.
⚡ One HLD concept. 60 seconds. Interview ready
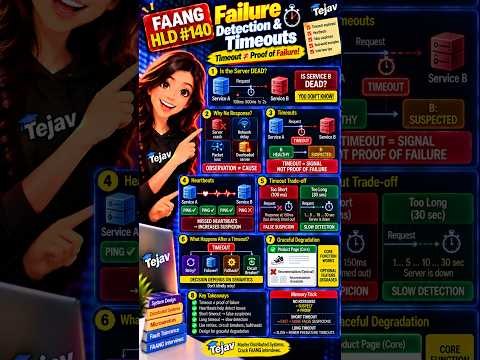
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Split Brain: Master Election and Quorum Explained
Elasticsearch uses master election and quorum to prevent split brain scenarios.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the RED Method for Microservices Monitoring
The RED Method helps monitor microservices using Rate, Errors, and Duration metrics.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Read Replicas in Database Scaling
Read replicas allow databases to handle more read requests by distributing them across multiple copies.
⚡ One HLD concept. 60 seconds. Interview ready
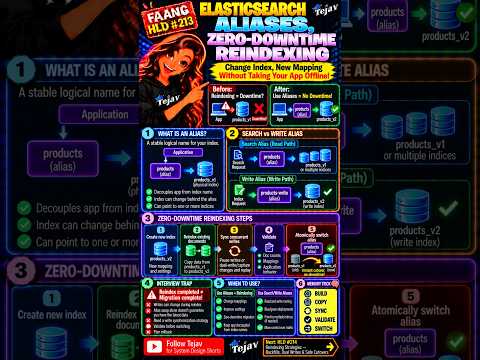
Elasticsearch Zero-Downtime Reindexing: The Alias Switch Trick
You can update Elasticsearch indices without downtime using alias switching.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.
⚡ One HLD concept. 60 seconds. Interview ready
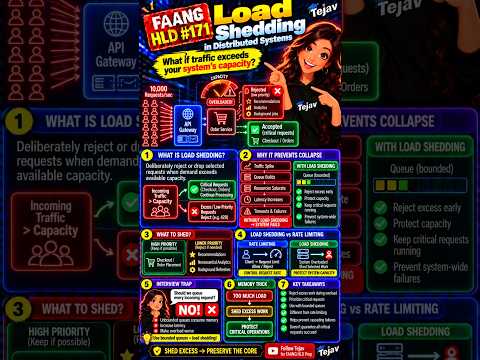
Load Shedding in Distributed Systems: Protecting Capacity
Load shedding helps systems reject excess requests to maintain performance during high demand.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Rebalance: Avoiding Work Loss or Duplication
Kafka rebalance can lead to lost or duplicated work if not handled carefully.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.