
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic1▾
Results · 28 for “Data Ranking Techniques”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Rescoring: Improve Search Result Rankings
Elasticsearch rescoring improves search result rankings using a two-stage process.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch BM25 & Field Boosting: Ranking Search Results
BM25 and field boosting help Elasticsearch rank search results based on relevance.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Function Score: Ranking with Business Signals
Elasticsearch's function_score combines text relevance with business signals for better rankings.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Downsampling and Aggregation in Time-Series Databases
Downsampling and aggregation reduce data volume while preserving essential trends.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Series Data Modeling: Avoiding Cardinality Issues
Choosing the right labels in time-series data is crucial to avoid inefficiencies.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Relevance Scoring with BM25
Elasticsearch ranks search results using BM25 based on relevance scoring.

⚡ One HLD concept. 60 seconds. Interview ready
Data Warehouse Architecture: Analyzing Business Data Efficiently
Data warehouses help businesses analyze large amounts of data for better decision-making.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: From & Size vs Search After
Elasticsearch offers two pagination methods: from & size for shallow pages and search_after for deep pages.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Based Partitioning: Scaling Time-Series Databases
Time-based partitioning organizes time-series data into smaller, efficient segments for better querying.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Hybrid Search: BM25 vs Vector Search
Elasticsearch Hybrid Search combines keyword and semantic searches for better results.
⚡ One HLD concept. 60 seconds. Interview ready
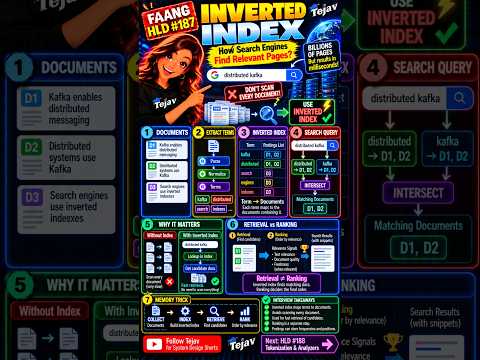
Inverted Index: How Search Engines Find Pages Efficiently
An inverted index helps search engines quickly find documents containing specific terms.
⚡ One HLD concept. 60 seconds. Interview ready
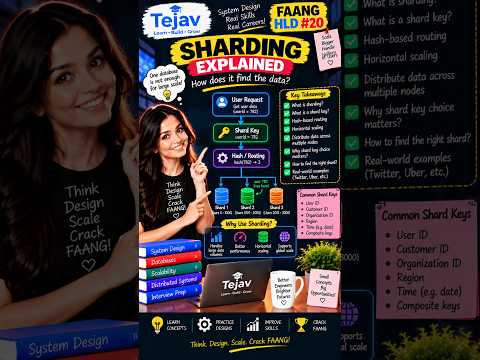
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Database Indexing: How to Make Queries Fast
Database indexing speeds up data retrieval by allowing quick lookups.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.

⚡ One HLD concept. 60 seconds. Interview ready
SQL vs NoSQL: Choosing the Right Database for Your Needs
The choice between SQL and NoSQL databases depends on your application's specific needs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Metrics vs Buckets Explained
Elasticsearch aggregations help summarize data using metrics for calculations and buckets for grouping.

⚡ One HLD concept. 60 seconds. Interview ready
Composite Indexes: Speed Up Multi-Column Queries in Databases
Composite indexes speed up database queries that filter or sort by multiple columns.

⚡ One HLD concept. 60 seconds. Interview ready
Time-Series Database Architecture: Storing Millions of Metrics
Time-series databases are designed to store and query time-stamped metrics efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.
⚡ One HLD concept. 60 seconds. Interview ready
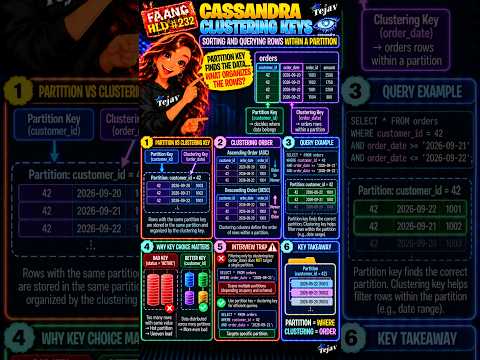
Cassandra Clustering Keys: How Rows Are Sorted
Cassandra uses clustering keys to sort rows within a partition for efficient querying.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Search Engine Architecture and Its Components
Search engines collect, index, retrieve, and rank documents to provide relevant results.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Partition Pruning Explained — Scan Less, Query Faster! ⚡
Partition pruning helps databases skip unnecessary data scans, speeding up queries.

⚡ One HLD concept. 60 seconds. Interview ready
Data Lake Architecture: Storing Big Data at Scale
Data lakes store large volumes of diverse data for analytics and processing.

⚡ One HLD concept. 60 seconds. Interview ready
MongoDB Sharding: Scaling to Millions of Orders
MongoDB uses sharding to distribute data across multiple servers for better scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Dynamo-Style Databases: High-Level Design Overview
Dynamo-style databases are designed for high availability and fault tolerance in distributed systems.