
QuestionHow does Elasticsearch decide which search results to show first?
Understanding Elasticsearch Relevance Scoring with BM25
- medium level
- 60-sec video
- 5-min read
- 5-question quiz
The big idea
Elasticsearch ranks search results using BM25 based on relevance scoring.
Your path
Log in to save progress
Explain it like I’m 10
Imagine you have a box of toys. If you ask for your favorite toy, the one you play with most often comes to the top. Elasticsearch does something similar with documents when you search for something.
Introduction to Elasticsearch Relevance Scoring
Elasticsearch is a powerful search engine that ranks documents based on their relevance to a given query. The scoring mechanism is crucial for determining which documents appear first in search results.
What is BM25?
BM25, or Best Matching 25, is the default algorithm used by Elasticsearch for scoring. It evaluates how well documents match search queries based on several factors:
- Term Frequency (TF): How often a search term appears in a document. More appearances generally lead to a higher score.
- Inverse Document Frequency (IDF): Rarer terms across the document collection provide more informative value, thus increasing the score.
- Field-Length Normalization: Longer fields may dilute the score, so normalization helps balance this effect.
Key Components of Relevance Scoring
- Match: Identify documents that contain the search terms.
- Score: Calculate the relevance score using BM25 or other scoring models.
- Rank: Order the documents based on their scores.
Field Boosting
Field boosting allows certain fields to have a greater influence on the score. For example, if product names are more important than descriptions, you can boost the name field by using a configuration like name^3, which gives it three times the weight in scoring.
Common Misconceptions
- Highest Score Equals Best Document: This is a trap! The highest score does not always mean the document is the best match for every query. Scores are context-dependent.
Conclusion
Understanding how Elasticsearch uses BM25 for relevance scoring is essential for optimizing search results and preparing for technical interviews. Knowing how term frequency, rarity, and field boosting work can significantly enhance your system design skills.
Example Scenario
Suppose you search for "best cricket bats". Elasticsearch will:
- Match documents containing these terms.
- Score them based on how often these terms appear and their rarity.
- Rank the documents so that the most relevant ones appear first.
Where you’ll see this
This scoring system is used in search engines, e-commerce platforms, and any application that requires effective document retrieval.
How exams test this
Exams may ask about the components of BM25 or how scoring affects ranking; a common trap is confusing score with quality.
📖 Words to know
- BM25
- An algorithm for scoring document relevance.
- Term Frequency
- How often a term appears in a document.
- Inverse Document Frequency
- A measure of how rare a term is across documents.
- Field Boosting
- Increasing the importance of specific fields in scoring.
Got it? Lock it in 🔒
5 quick questions. Students who test themselves remember far more than those who just re-read.
30-second revision card
- 1BM25 is the default scoring algorithm in Elasticsearch.
- 2Term Frequency increases a document's score based on keyword occurrences.
- 3Inverse Document Frequency boosts scores for rare terms.
- 4Field-length normalization adjusts scores based on field size.
- 5Field boosting enhances the importance of specific fields.
Memory trick
BM25: Boost Matches by 25% for better relevance!
🧠 Recall check
Answer in your head, then tap to flip. Recalling beats re-reading.
Myth vs Fact
❌ Myth: Higher scores always mean better documents.
✅ Fact: Scores are context-dependent and not universally comparable.
❌ Myth: BM25 is the only scoring method.
✅ Fact: Elasticsearch allows for other scoring models as well.
Ready to prove it? 🎯
You’ve revised the essentials. See how much actually stuck.
Question 1 of 5
Log in to take the quiz and lock this concept in
- 🎯Instant answers & explanationsSee why each answer is right, and the trap in the wrong ones.
- 📍Continue where you left offYour progress follows you on every device.
- 🧠Smart revision remindersTopics come back after 1 → 3 → 7 → 21 → 60 days, right before you’d forget.
- 🔥Streaks & activity heatmapBuild a daily habit, one short at a time.
- 📊Your weak spots, found for youSee which concepts need work and practise just those.
- 🔖Save topics for laterBookmark shorts to revisit before exams.
No credit card. Watching and reading stay free without an account.
Learn next
Watch first
Course outline · 220 topics
- 1What FAANG Interviewers Evaluate in System Design Interviews
- 2Understanding High-Level Design (HLD) and Low-Level Design (LLD)
- 3Understanding Functional and Non-Functional Requirements
- 4Understanding Scalable System Design in FAANG Companies
- 5Understanding Latency, Throughput, and Response Time
- 6Understanding Availability vs Reliability in System Design
- 7Understanding Latency and Throughput in System Design
- 8Understanding Vertical and Horizontal Scaling in System Design
- 9Stateless vs Stateful Servers: Scaling Made Easy
- 10Monolith vs Microservices: Choosing the Right Architecture
- 11Understanding Load Balancers in System Design
- 12L4 vs L7 Load Balancers: Key Differences Explained
- 13Understanding Reverse Proxy in High-Level Design
- 14Understanding CDN: How Cache Hits Improve Performance
- 15Understanding Cache Hits: Reducing Database Load
- 16Understanding the Cache-Aside Pattern in System Design
- 17Redis: Why Is It So Fast for High-Scale Systems?
- 18SQL vs NoSQL: Choosing the Right Database for Your Needs
- 19Understanding Database Replication in High-Level Design
- 20Understanding Sharding: How Databases Manage Large Data
- 21FAANG HLD 🔥 | Partition Pruning Explained — Scan Less, Query Faster! ⚡
- 22B-Tree Index: Efficient Database Navigation
- 23Read-After-Write Consistency in Database Systems
- 24Understanding Read Replicas in Database Scaling
- 25Identifying and Optimizing Database Bottlenecks
- 26Understanding CAP Theorem: Trade-offs in Distributed Systems
- 27Understanding Consistency Models in Distributed Systems
- 28Understanding Quorum Reads in Distributed Systems
- 29Leader Election in Distributed Systems: Handling Leader Failures
- 30Log Replication and Majority Commit in Distributed Systems
- 31Consistent Hashing: Key to Distributed Systems Scalability
- 32Distributed Caching: Why Spread It Out?
- 33Cache Eviction Policies: LRU, LFU, and FIFO Explained
- 34Cache Invalidation: TTL vs Freshness Explained
- 35Understanding Cache Stampede in High-Level Design
- 36Understanding Cache Penetration in System Design
- 37Understanding Cache Breakdown and Request Coalescing
- 38Token Bucket Rate Limiting Explained for Interviews
- 39Token Bucket vs Leaky Bucket: Key Differences Explained
- 40API Gateway: The Front Door of Your System
- 41API Gateway vs Proxy vs Load Balancer: Key Differences
- 42Service Discovery in Microservices Architecture
- 43DNS Service Discovery: Is DNS Enough for Microservices?
- 44Understanding DNS Record Types: A, CNAME, MX, and More
- 45Understanding DNS Resolution: How URLs Load in Browsers
- 46Understanding TCP 3-Way Handshake: SYN, SYN-ACK, ACK
- 47Understanding the TLS Handshake in HTTPS Connections
- 48HTTP vs HTTPS: Understanding the Key Differences
- 49Understanding HTTP Methods and Status Codes
- 50REST API Design: Building Scalable APIs for Real-World Use
- 51API Pagination: Efficiently Handling Large Datasets
- 52Database Indexing: How to Make Queries Fast
- 53Composite Indexes: Speed Up Multi-Column Queries in Databases
- 54Read vs Write Scaling: How to Scale Databases
- 55Database Replication: Scale and Survive Failures
- 56Sync vs Async Replication: Choosing the Right Approach
- 57Failover and Split-Brain in High-Level Design
- 58Understanding Write-Ahead Log (WAL) in Databases
- 59Understanding Transactions and ACID Properties in Databases
- 60Understanding Database Isolation Levels in Software Engineering
- 61Optimistic vs Pessimistic Locking in Database Management
- 62Understanding 2-Phase Commit in Distributed Transactions
- 63Understanding the Saga Pattern in Distributed Transactions
- 64Transactional Outbox Pattern: Never Lose Events!
- 65Understanding Idempotency in System Design
- 66Understanding Message Queues in Distributed Systems
- 67Queue vs Pub/Sub: Key Differences in System Design
- 68Understanding Apache Kafka for Scalable Event Streaming
- 69Understanding Kafka Partitioning for Scalable Messaging
- 70Message Delivery Semantics: At-Most-Once vs At-Least-Once vs Exactly-Once
- 71Understanding Kafka Consumer Lag and Its Impact
- 72Kafka Retention vs Compaction: History or Latest State?
- 73Kafka Exactly-Once Processing: Avoiding Duplicates
- 74Kafka Schema Evolution: Changing Schemas Without Breaking Consumers
- 75Kafka Producer Reliability: ACKs, Retries & Idempotence
- 76Kafka Ordering and Keys: Ensuring Message Order
- 77Kafka Consumer Offsets: Auto Commit vs Manual Commit
- 78Understanding Kafka Retries and Dead Letter Queue (DLQ)
- 79FAANG HLD 🔥 | Kafka Backpressure Explained — What Happens When Consumers Can't Keep Up? 🚨
- 80Understanding Kafka Brokers, Controllers, and KRaft Architecture
- 81Kafka Replication and ISR: Ensuring Data Availability
- 82Kafka Partition Reassignment: Move Replicas Without Data Loss
- 83Kafka Consumer Group Rebalancing Explained
- 84Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
- 85Kafka Consumer Liveness: Heartbeats, Sessions & Timeouts Explained
- 86Kafka Consumer Lag Monitoring: Prevent Production Issues
- 87Kafka Lag Recovery Time: How Fast Can Consumers Catch Up?
- 88Kafka Consumer Fetch & Batching: Boosting Throughput
- 89Kafka Fetch Limits vs Poll Records: Understanding the Difference
- 90Kafka Eager vs Cooperative Rebalancing: Key Differences
- 91Kafka Static Membership: Reducing Unnecessary Rebalancing
- 92Understanding Kafka Rebalance Listeners in High-Level Design
- 93Understanding Kafka Offset Reset: Earliest vs Latest
- 94Kafka Replay Safely: Reprocess Messages Without Losing Data
- 95Kafka Commit Strategies: Auto vs Manual Commit Explained
- 96Kafka commitSync vs commitAsync: Choosing the Right Method
- 97Kafka Async Commit Ordering: Can Older Offsets Overwrite Newer Ones?
- 98Kafka Consumer Concurrency: Understanding Partitions and Threads
- 99Kafka Consumer Multithreading: Processing Messages in Parallel
- 100Kafka Consumer Parallelism: Partitions, Keys, and Throughput
- 101Kafka Consumer Pause & Resume: Managing Backpressure Smartly
- 102Kafka Backpressure Strategies: Handling Traffic Spikes
- 103Kafka Graceful Shutdown: Stop Without Losing Work
- 104Kafka Error Handling and Retry Strategies in HLD
- 105Kafka Retry Topics and Delayed Retries Explained
- 106Understanding Kafka Dead Letter Topics and Poison Messages
- 107Kafka Poison Messages: Risks of Infinite Retries
- 108Kafka Consumer Reprocessing: Safe Event Replay Strategies
- 109Kafka Replay Without Breaking Production: Safe Architecture
- 110Kafka Pause vs Seek: Key Differences Explained
- 111FAANG HLD 🔥 | Kafka Seek — Replay Specific Messages Without Replaying Everything! 🎯
- 112Kafka subscribe() vs assign(): Who Controls Partition Assignment?
- 113Kafka Manual Partition Assignment: Using assign() for Control
- 114Kafka Rebalance: Avoiding Work Loss or Duplication
- 115Kafka Consumer Crash Recovery: Resuming Processing Explained
- 116Kafka Consumer State: Position, Offset, and Business State
- 117Kafka Stateful Stream Processing: How Does It Remember?
- 118Kafka Streams vs Consumer: Choosing the Right Tool
- 119Kafka Streams Local State: Fast Processing and Recovery
- 120Kafka Streams Windowing: Tumbling vs Hopping Windows Explained
- 121Distributed Locks: Preventing Duplicate Work Across Servers
- 122Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
- 123Leader Election in Distributed Systems Explained
- 124Leader Election Algorithms: Bully vs Raft vs ZooKeeper
- 125Understanding Consensus in Distributed Systems
- 126Understanding Raft Consensus: Terms, Elections & Log Replication
- 127Understanding Raft Log Replication: matchIndex vs commitIndex
- 128Raft Leader Failure and Re-election Process Explained
- 129FAANG HLD 🔥 | Raft Safety — Why Committed Entries Survive Leader Failure! 🛡️
- 130Understanding Quorum and Majority in Distributed Systems
- 131Paxos Consensus: Understanding Distributed Agreement
- 132FAANG HLD 🔥 | Raft vs Paxos — What's the Difference? Consensus Explained! ⚡
- 133ZooKeeper Architecture and ZAB Explained
- 134Understanding ZooKeeper Ephemeral and Sequential Nodes
- 135ZooKeeper Watches: Avoiding the Thundering Herd Problem
- 136HLD: Crash Failures vs Network Failures in Distributed Systems
- 137HLD: Fail-Stop vs Fail-Recover Explained
- 138Understanding Network Partitions in Distributed Systems
- 139Understanding Partial Failure in Distributed Systems
- 140HLD: Understanding Server Failure Detection and Timeouts
- 141Understanding Distributed Clocks in Systems Design
- 142Understanding Physical vs Logical Time in Distributed Systems
- 143Understanding Lamport Timestamps in Distributed Systems
- 144Understanding Vector Clocks in Distributed Systems
- 145Understanding Causality in Distributed Systems
- 146Understanding RPC: Remote Procedure Calls in Distributed Systems
- 147HLD: Understanding REST, RPC, and gRPC Differences
- 148Understanding gRPC Architecture: Behind the Call
- 149Protobuf and Schema Evolution: Avoid Breaking Changes
- 150Understanding Unary vs Streaming RPC in gRPC
- 151HLD: Synchronous vs Asynchronous Communication Explained
- 152HLD: Understanding Request-Response vs Events in System Design
- 153HLD: 5 Microservices Communication Patterns Explained
- 154Connection Pooling Explained: Why a Bigger Pool Can Hurt
- 155Keep-Alive in Networking: Efficient HTTP Connections
- 156When to Use Microservices in Software Design
- 157HLD: Microservices vs Modular Monolith Explained
- 158Choosing Service Boundaries in Microservices Architecture
- 159Understanding Database per Service in Microservices Architecture
- 160HLD: Shared DB vs Database per Service Trade-Offs
- 161HLD: Circuit Breaker Explained to Prevent Failures
- 162Understanding the Retry Pattern in System Design
- 163HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
- 164Understanding the Bulkhead Pattern in System Design
- 165HLD: Fallbacks Explained for System Design
- 166Understanding Retry Storms in Distributed Systems
- 167Exponential Backoff: Managing Retry Storms in Systems
- 168Understanding Jitter in High-Level Design
- 169Understanding Circuit Breaker: CLOSED, OPEN, and HALF-OPEN States
- 170Cascading Failures in Distributed Systems Explained
- 171Load Shedding in Distributed Systems: Protecting Capacity
- 172Graceful Degradation in System Design
- 173Distributed Backpressure: Managing Service Overload
- 174HLD: Fail Fast vs Fail Safe in System Design
- 175HLD: Managing Dependency Failures in Distributed Systems
- 176Understanding Logs, Metrics, and Traces in Software Engineering
- 177Observability in Distributed Systems: Debugging Production Issues
- 178Structured Logging: Debugging Production Issues Faster
- 179Understanding Correlation IDs in Microservices Architecture
- 180Understanding Distributed Tracing in Microservices Architecture
- 181Understanding the RED Method for Microservices Monitoring
- 182Understanding the USE Method for Infrastructure Bottlenecks
- 183Understanding SLIs, SLOs, and SLAs in Reliability Engineering
- 184Understanding Error Budgets in High-Level Design
- 185Understanding Alerting in High-Level Design
- 186HLD: Search Engine Architecture and Its Components
- 187Inverted Index: How Search Engines Find Pages Efficiently
- 188HLD: Tokenization and Analyzers in Search Engines
- 189HLD: Stemming and Normalization in Search Engines
- 190HLD: Full-Text Search vs Database Search with Elasticsearch
- 191Elasticsearch Architecture: How Distributed Search Works
- 192Elasticsearch Shards vs Replicas: Partitioning vs Duplication
- 193Elasticsearch Indexing: Why Can't You Search Your Document Yet?
- 194Elasticsearch Query Execution: How Searches Work Across Shards
- 195Elasticsearch Refresh: Why Your Document Isn’t Searchable Yet
- 196Understanding Elasticsearch Relevance Scoring with BM25
- 197Elasticsearch Filters vs Queries: MUST vs FILTER Explained
- 198Elasticsearch Aggregations: Metrics vs Buckets Explained
- 199Elasticsearch Pagination: From & Size vs Search After
- 200Understanding Elasticsearch ILM: Hot, Warm, Cold Phases
- 201Elasticsearch Aliases and Rollover: Zero-Downtime Index Switching
- 202Understanding Elasticsearch Data Streams in HLD
- 203Understanding Elasticsearch Index Templates and Components
- 204Elasticsearch Mapping: Dynamic vs Explicit Explained
- 205Understanding Elasticsearch Shards and Replicas in HLD
- 206Elasticsearch Cluster Sizing: How Many Nodes Do You Need?
- 207Understanding Elasticsearch Node Roles for Scaling Clusters
- 208Elasticsearch Split Brain: Master Election and Quorum Explained
- 209Understanding Elasticsearch Snapshots: Replicas vs Backups
- 210Understanding Elasticsearch Cross-Cluster Replication (CCR)
- 211Understanding Elasticsearch ILM for Cost Management
- 212Elasticsearch Data Streams vs. Time-Based Indices: Which to Choose?
- 213Elasticsearch Zero-Downtime Reindexing: The Alias Switch Trick
- 214Elasticsearch Reindexing: Understanding the Dual-Write Trap
- 215Elasticsearch Query Optimization: Filters and Caching
- 216Elasticsearch Pagination: Fixing Slow Page Searches
- 217Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
- 218Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
- 219Elasticsearch Fuzzy Search: Handling Typos in Queries
- 220Understanding Elasticsearch Synonyms and Analyzers
Connected concepts

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Query Optimization: Filters and Caching
Optimizing Elasticsearch involves using filters, caching, and measuring performance.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Synonyms and Analyzers
Elasticsearch uses analyzers and synonyms to improve search accuracy by connecting similar words.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Filters vs Queries: MUST vs FILTER Explained
Filters check conditions without affecting relevance, while queries do.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Metrics vs Buckets Explained
Elasticsearch aggregations help summarize data using metrics for calculations and buckets for grouping.
⚡ One HLD concept. 60 seconds. Interview ready
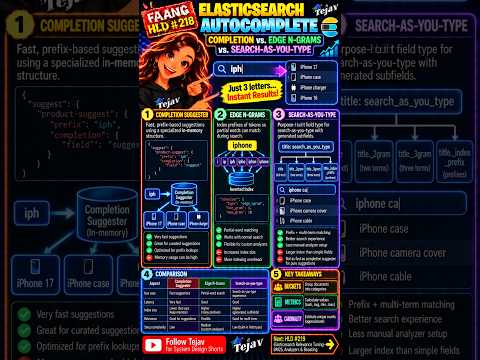
Elasticsearch Autocomplete: Completion vs. Edge N-Grams vs. Search-as-You-Type
Elasticsearch offers three main autocomplete strategies, each with unique benefits and trade-offs.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Aggregations: Buckets, Metrics, and Cardinality
Elasticsearch aggregations help analyze data by grouping, calculating, and estimating values.