
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic▾
Results · 32 for “Connection Pooling”
← Front page✨ Smart search: matched by meaning, not just words
⚡ One HLD concept. 60 seconds. Interview ready
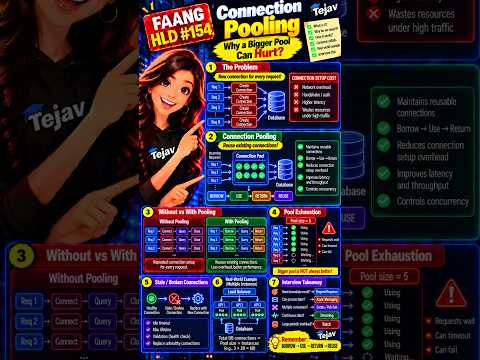
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
Keep-Alive in Networking: Efficient HTTP Connections
Keep-Alive allows reusing HTTP connections to improve efficiency and reduce overhead.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.
⚡ One HLD concept. 60 seconds. Interview ready
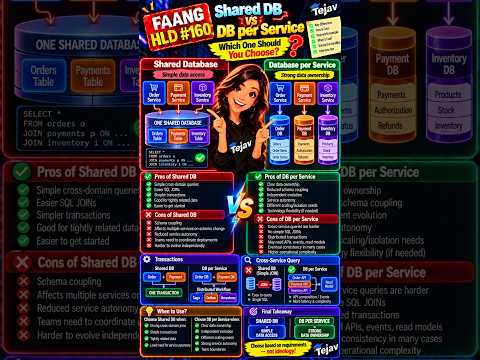
HLD: Shared DB vs Database per Service Trade-Offs
Choosing between a shared database and a database per service affects system design significantly.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Consistent Hashing: Key to Distributed Systems Scalability
Consistent hashing helps distribute data across servers with minimal movement.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Static Membership: Reducing Unnecessary Rebalancing
Kafka's static membership allows consumers to maintain stable identities, reducing unnecessary rebalances.
⚡ One HLD concept. 60 seconds. Interview ready
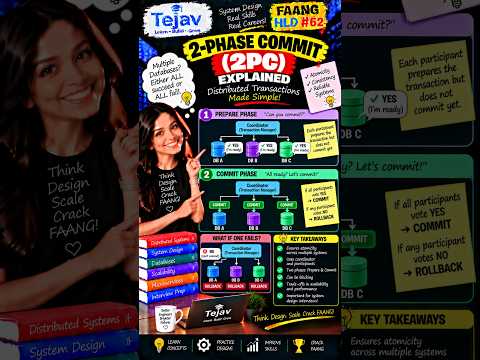
Understanding 2-Phase Commit in Distributed Transactions
2-Phase Commit helps maintain data consistency in transactions across multiple databases.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.
⚡ One HLD concept. 60 seconds. Interview ready
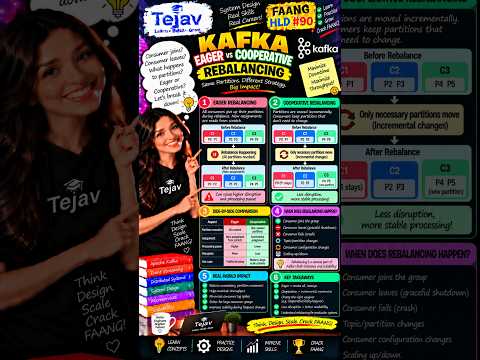
Kafka Eager vs Cooperative Rebalancing: Key Differences
Eager rebalancing revokes all assignments, while cooperative allows incremental changes.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Assignment Strategies: Range vs RoundRobin vs Sticky
Kafka uses different strategies to assign partitions to consumers in a group efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.

⚡ One HLD concept. 60 seconds. Interview ready
Service Discovery in Microservices Architecture
Service Discovery helps microservices locate each other dynamically without fixed IP addresses.

⚡ One HLD concept. 60 seconds. Interview ready
Token Bucket vs Leaky Bucket: Key Differences Explained
Token Bucket allows burst traffic, while Leaky Bucket smooths out traffic flow.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Unary vs Streaming RPC in gRPC
gRPC supports four communication patterns: Unary, Server Streaming, Client Streaming, and Bidirectional Streaming.

⚡ One HLD concept. 60 seconds. Interview ready
ZooKeeper Architecture and ZAB Explained
ZooKeeper coordinates distributed systems using an ensemble of servers and the ZAB protocol.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding ZooKeeper Ephemeral and Sequential Nodes
ZooKeeper uses ephemeral and sequential nodes for managing distributed services effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.