
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic▾
Results · 60 for “Distributed Database Systems”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
SQL vs NoSQL: Choosing the Right Database for Your Needs
The choice between SQL and NoSQL databases depends on your application's specific needs.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Shared DB vs Database per Service Trade-Offs
Choosing between a shared database and a database per service affects system design significantly.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Sharding: How Databases Manage Large Data
Sharding splits databases into smaller parts to improve performance and scalability.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Replication in High-Level Design
Database replication enhances data availability and read performance but has challenges like replication lag.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing a Distributed Lock: Redis vs Database vs ZooKeeper
Choosing the right distributed lock depends on your system's needs and existing tools.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Locks: Preventing Duplicate Work Across Servers
Distributed locks ensure only one server performs a task, avoiding duplication.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Transactions and ACID Properties in Databases
Transactions ensure database operations are reliable using ACID properties.

⚡ One HLD concept. 60 seconds. Interview ready
B-Tree Index: Efficient Database Navigation
B-Trees help databases find data quickly without scanning every row.

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
Identifying and Optimizing Database Bottlenecks
Database bottlenecks slow down performance, but identifying them helps optimize and scale effectively.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Full-Text Search vs Database Search with Elasticsearch
Choose Elasticsearch for complex text searches, but use databases for structured queries.

⚡ One HLD concept. 60 seconds. Interview ready
Failover and Split-Brain in High-Level Design
Failover ensures systems remain operational by managing leader changes during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Read Replicas in Database Scaling
Read replicas allow databases to handle more read requests by distributing them across multiple copies.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database Isolation Levels in Software Engineering
Database isolation levels determine how transactions interact and affect data consistency.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Distributed Clocks in Systems Design
In distributed systems, timestamps don't always reflect the true order of events.

⚡ One HLD concept. 60 seconds. Interview ready
Read-After-Write Consistency in Database Systems
Read-after-write consistency ensures users see their latest updates immediately.

⚡ One HLD concept. 60 seconds. Interview ready
Read vs Write Scaling: How to Scale Databases
Scaling databases involves deciding whether to enhance read or write capabilities based on traffic patterns.

⚡ One HLD concept. 60 seconds. Interview ready
Consistent Hashing: Key to Distributed Systems Scalability
Consistent hashing helps distribute data across servers with minimal movement.

⚡ One HLD concept. 60 seconds. Interview ready
Sync vs Async Replication: Choosing the Right Approach
Synchronous replication waits for confirmation from replicas, while asynchronous allows faster writes without waiting.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.

⚡ One HLD concept. 60 seconds. Interview ready
Log Replication and Majority Commit in Distributed Systems
Log replication ensures data consistency by requiring majority acknowledgment before committing changes.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Message Queues in Distributed Systems
Message queues allow services to communicate asynchronously, improving scalability and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Architecture: How Distributed Search Works
Elasticsearch uses distributed architecture to search data quickly across multiple servers.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Write-Ahead Log (WAL) in Databases
Write-Ahead Log ensures data is safely recorded before changes are made.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding 2-Phase Commit in Distributed Transactions
2-Phase Commit helps maintain data consistency in transactions across multiple databases.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Quorum Reads in Distributed Systems
Quorum Reads ensure data consistency by querying multiple replicas in distributed systems.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Database Indexing: How to Make Queries Fast
Database indexing speeds up data retrieval by allowing quick lookups.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Backpressure: Managing Service Overload
Distributed backpressure helps manage the flow of work between services to prevent overload.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Lamport Timestamps in Distributed Systems
Lamport Timestamps help order events in distributed systems while preserving causality.
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Hits: Reducing Database Load
Caching helps applications respond faster by serving data from memory instead of hitting the database.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Load Balancers in System Design
Load balancers distribute traffic across multiple servers to enhance performance and reliability.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.
⚡ One HLD concept. 60 seconds. Interview ready
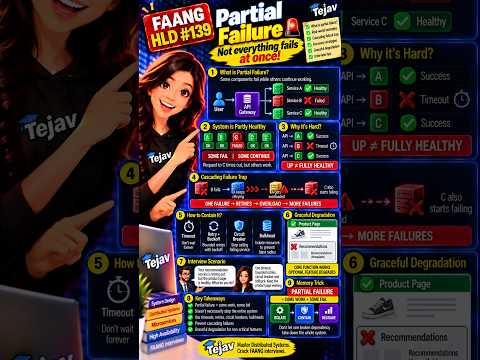
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
ZooKeeper Watches: Avoiding the Thundering Herd Problem
ZooKeeper watches notify clients of changes, avoiding constant polling and reducing server load.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.
⚡ One HLD concept. 60 seconds. Interview ready
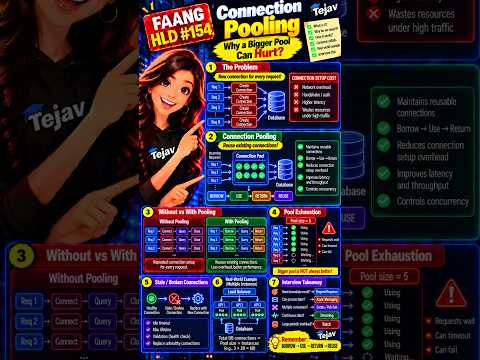
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Saga Pattern in Distributed Transactions
The Saga Pattern manages distributed transactions using local transactions and compensating actions.

⚡ One HLD concept. 60 seconds. Interview ready
ZooKeeper Architecture and ZAB Explained
ZooKeeper coordinates distributed systems using an ensemble of servers and the ZAB protocol.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Scalable System Design in FAANG Companies
FAANG engineers use high-level design principles to create scalable systems.

⚡ One HLD concept. 60 seconds. Interview ready
HLD Timeout Pattern: Understanding Timeouts in Distributed Systems
A timeout indicates a deadline was exceeded, not necessarily a failure.
⚡ One HLD concept. 60 seconds. Interview ready
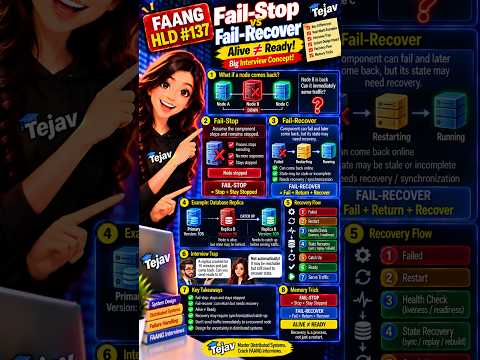
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Leader Election in Distributed Systems Explained
Leader election helps distributed systems select one coordinator from many nodes.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Split Brain: Master Election and Quorum Explained
Elasticsearch uses master election and quorum to prevent split brain scenarios.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.
⚡ One HLD concept. 60 seconds. Interview ready
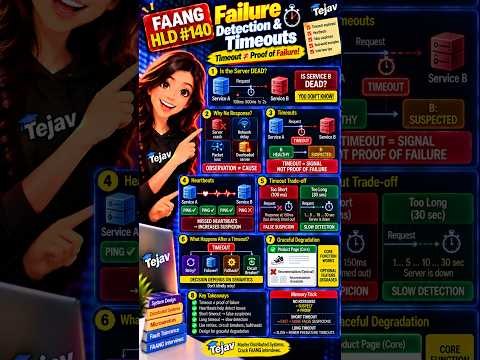
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.
⚡ One HLD concept. 60 seconds. Interview ready
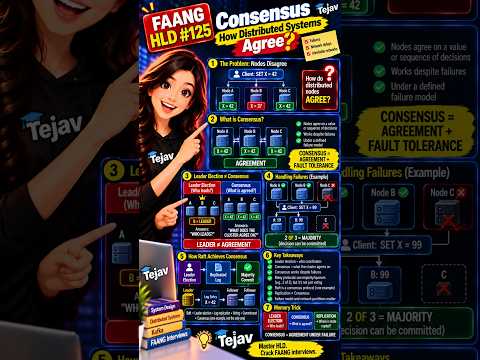
Understanding Consensus in Distributed Systems
Consensus ensures that distributed systems can agree on decisions even during failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.