
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic▾
Results · 26 for “Knowledge of service reliability”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding SLIs, SLOs, and SLAs in Reliability Engineering
SLIs measure service performance, SLOs set reliability targets, and SLAs are customer agreements.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Availability vs Reliability in System Design
Availability is about access; reliability is about correct performance.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the RED Method for Microservices Monitoring
The RED Method helps monitor microservices using Rate, Errors, and Duration metrics.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Error Budgets in High-Level Design
An error budget shows how much downtime is acceptable while meeting reliability goals.

⚡ One HLD concept. 60 seconds. Interview ready
Service Discovery in Microservices Architecture
Service Discovery helps microservices locate each other dynamically without fixed IP addresses.
⚡ One HLD concept. 60 seconds. Interview ready
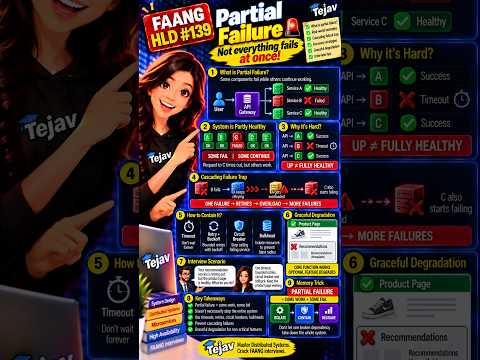
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Observability in Distributed Systems: Debugging Production Issues
Observability helps engineers understand system behavior to debug production issues effectively.
⚡ One HLD concept. 60 seconds. Interview ready
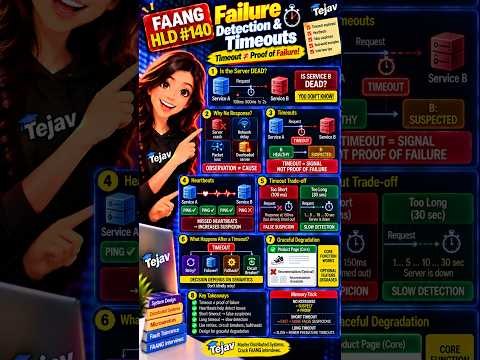
HLD: Understanding Server Failure Detection and Timeouts
Timeouts in distributed systems indicate suspicion, not confirmed failure.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Choosing Service Boundaries in Microservices Architecture
Choosing the right boundaries for microservices is crucial for effective architecture.
⚡ One HLD concept. 60 seconds. Interview ready
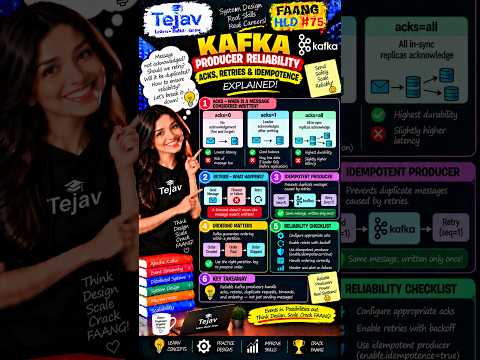
Kafka Producer Reliability: ACKs, Retries & Idempotence
Kafka producers use ACKs, retries, and idempotence to ensure reliable message delivery.

⚡ One HLD concept. 60 seconds. Interview ready
DNS Service Discovery: Is DNS Enough for Microservices?
DNS helps microservices find each other, but it has limitations that may require a service registry.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.
⚡ One HLD concept. 60 seconds. Interview ready
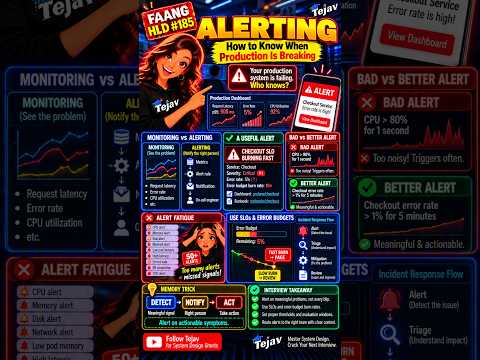
Understanding Alerting in High-Level Design
Alerting helps notify the right people about production issues quickly.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.
⚡ One HLD concept. 60 seconds. Interview ready
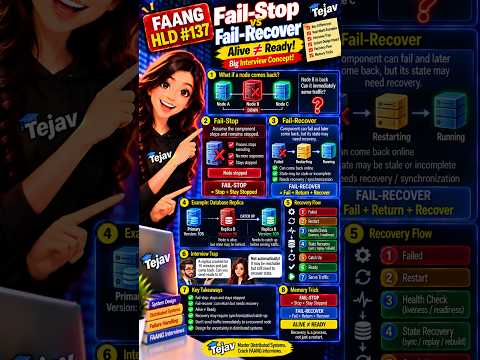
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the USE Method for Infrastructure Bottlenecks
The USE Method helps find and analyze infrastructure bottlenecks in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Correlation IDs in Microservices Architecture
Correlation IDs help track requests in microservices for easier debugging.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.
⚡ One HLD concept. 60 seconds. Interview ready
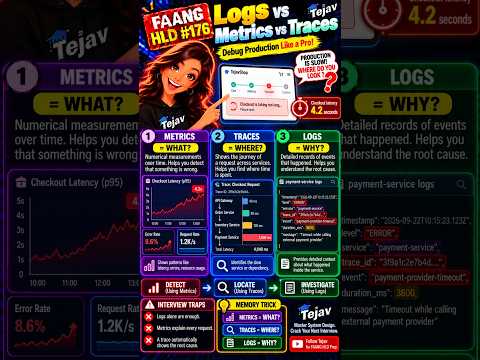
Understanding Logs, Metrics, and Traces in Software Engineering
Logs, metrics, and traces help engineers debug issues in software systems.

⚡ One HLD concept. 60 seconds. Interview ready
When to Use Microservices in Software Design
Microservices are useful when you need independent scaling, deployment, and clear boundaries in software design.