
I'm preparing for
🎛️ Narrow down IT & Codingsubject · level · topic▾
Results · 20 for “Resilience Patterns”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Bulkhead Pattern in System Design
The Bulkhead Pattern isolates resources to protect critical workloads from failures.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Circuit Breaker Explained to Prevent Failures
A Circuit Breaker helps prevent system failures by stopping calls to unhealthy services.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: 5 Microservices Communication Patterns Explained
Microservices can communicate using five key patterns based on their needs.
⚡ One HLD concept. 60 seconds. Interview ready
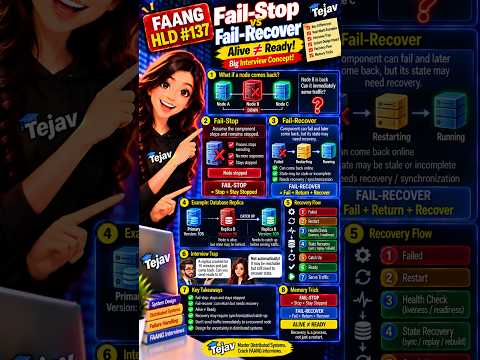
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Circuit Breaker: CLOSED, OPEN, and HALF-OPEN States
The Circuit Breaker pattern controls service calls to prevent failures from spreading.
⚡ One HLD concept. 60 seconds. Interview ready
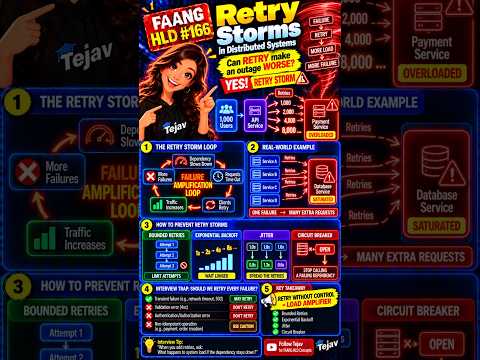
Understanding Retry Storms in Distributed Systems
Retry storms occur when too many retries overload a failing service.

⚡ One HLD concept. 60 seconds. Interview ready
Exponential Backoff: Managing Retry Storms in Systems
Exponential backoff helps manage retries by increasing wait times to reduce system overload.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.
⚡ One HLD concept. 60 seconds. Interview ready
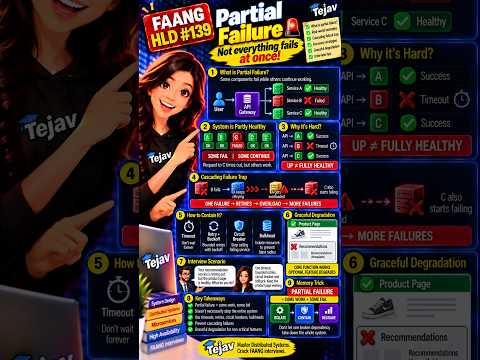
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Crash Recovery: Resuming Processing Explained
Kafka consumers resume processing from the last committed offset after a crash.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Unary vs Streaming RPC in gRPC
gRPC supports four communication patterns: Unary, Server Streaming, Client Streaming, and Bidirectional Streaming.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Understanding Request-Response vs Events in System Design
Request-Response asks for a result, while Events notify that something has happened.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retry Topics and Delayed Retries Explained
Kafka uses retry topics and delayed retries to manage message failures efficiently.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Error Handling and Retry Strategies in HLD
Classifying failures and using controlled retries in Kafka prevents outages.