
I'm preparing for
🎛️ Narrow downsubject · level · topic1▾
Results · 23 for “Crash Recovery Concepts”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Crash Recovery: Resuming Processing Explained
Kafka consumers resume processing from the last committed offset after a crash.
⚡ One HLD concept. 60 seconds. Interview ready
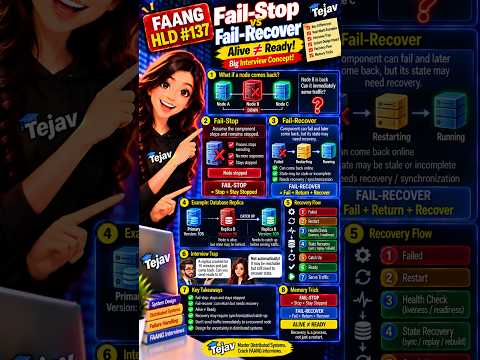
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Crash Failures vs Network Failures in Distributed Systems
Crash failures stop a service, while network failures disrupt communication.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Lag Recovery Time: How Fast Can Consumers Catch Up?
Kafka lag recovery time is how fast consumers can process backlogged messages.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Network Partitions in Distributed Systems
Network partitions occur when servers are operational but can't communicate, affecting system performance.

⚡ One HLD concept. 60 seconds. Interview ready
FAANG HLD 🔥 | Raft Safety — Why Committed Entries Survive Leader Failure! 🛡️
Raft's safety rules guarantee that committed entries are preserved even after leader failures.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Commit Strategies: Auto vs Manual Commit Explained
Kafka commit strategies determine how offsets are managed during message processing.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Streams Local State: Fast Processing and Recovery
Kafka Streams uses local state for quick data access and changelogs for recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding RPC: Remote Procedure Calls in Distributed Systems
RPC allows one service to call a function in another service over the network.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Raft Consensus: Terms, Elections & Log Replication
Raft consensus helps distributed systems elect leaders and replicate logs reliably.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Rebalance: Avoiding Work Loss or Duplication
Kafka rebalance can lead to lost or duplicated work if not handled carefully.
⚡ One HLD concept. 60 seconds. Interview ready
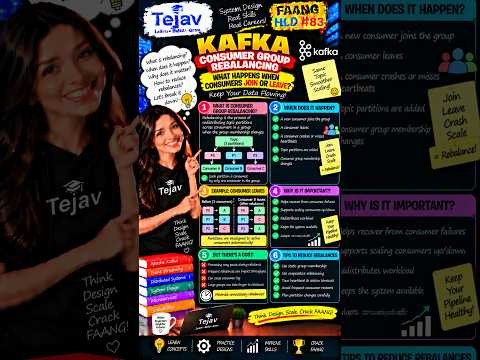
Kafka Consumer Group Rebalancing Explained
Kafka rebalances consumer groups to manage partition assignments effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Log Replication and Majority Commit in Distributed Systems
Log replication ensures data consistency by requiring majority acknowledgment before committing changes.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Pause & Resume: Managing Backpressure Smartly
Kafka consumers can pause and resume message processing to handle backpressure effectively.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Stateful Stream Processing: How Does It Remember?
Kafka uses state stores to remember previous events in stateful stream processing.
⚡ One HLD concept. 60 seconds. Interview ready
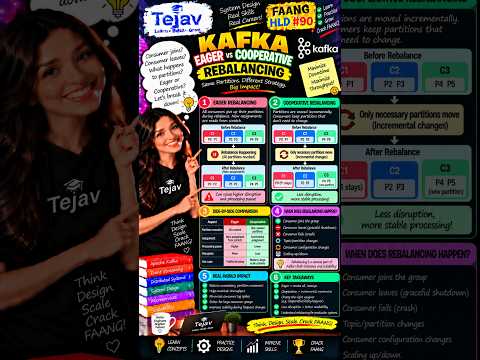
Kafka Eager vs Cooperative Rebalancing: Key Differences
Eager rebalancing revokes all assignments, while cooperative allows incremental changes.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Offsets: Auto Commit vs Manual Commit
Kafka consumer offsets help track message processing to avoid loss and duplication.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Split Brain: Master Election and Quorum Explained
Elasticsearch uses master election and quorum to prevent split brain scenarios.

⚡ One HLD concept. 60 seconds. Interview ready
Raft Leader Failure and Re-election Process Explained
Raft handles leader failure by allowing followers to elect a new leader through voting.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Async Commit Ordering: Can Older Offsets Overwrite Newer Ones?
Older offsets can overwrite newer ones in Kafka if not handled properly.