
I'm preparing for
🎛️ Narrow downsubject · level · topic1▾
Results · 35 for “Redis persistence”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Redis: Why Is It So Fast for High-Scale Systems?
Redis is a fast in-memory data store used for caching and low-latency applications.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Idempotency in System Design
Idempotency ensures that repeated operations in APIs do not cause duplicate effects.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Database per Service in Microservices Architecture
Database per Service ensures each microservice owns its data, reducing dependencies.

⚡ One HLD concept. 60 seconds. Interview ready
Read-After-Write Consistency in Database Systems
Read-after-write consistency ensures users see their latest updates immediately.

⚡ One HLD concept. 60 seconds. Interview ready
Stateless vs Stateful Servers: Scaling Made Easy
Stateless servers are easier to scale because they don't store user session data locally.

⚡ One HLD concept. 60 seconds. Interview ready
Transactional Outbox Pattern: Never Lose Events!
The Transactional Outbox Pattern ensures database updates and event publishing are synchronized to avoid losing events.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Penetration in System Design
Cache penetration occurs when requests for non-existent data overload the database.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Retention vs Compaction: History or Latest State?
Kafka uses retention to keep historical data and compaction to keep the latest state.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Consistency Models in Distributed Systems
Consistency models determine what data reads in distributed systems can see.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Cache-Aside Pattern in System Design
The Cache-Aside Pattern speeds up data retrieval by using a cache to store frequently accessed data.
⚡ One HLD concept. 60 seconds. Interview ready
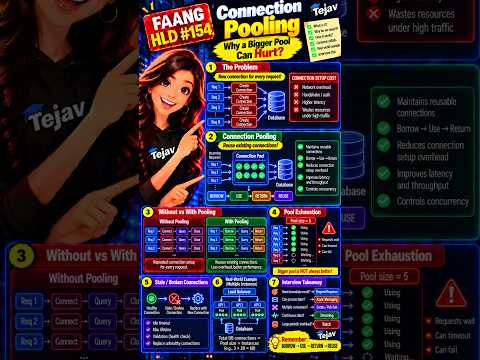
Connection Pooling Explained: Why a Bigger Pool Can Hurt
Connection pooling reuses database connections but can cause issues if misconfigured.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Stampede in High-Level Design
Cache stampede occurs when many requests hit the database due to a cache miss.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Poison Messages: Risks of Infinite Retries
Poison messages in Kafka can cause infinite retries, risking system stability.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Cache Breakdown and Request Coalescing
Cache breakdowns can overwhelm databases, but request coalescing solves this issue.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Exactly-Once Processing: Avoiding Duplicates
Kafka can help ensure messages are processed once, but requires careful design.

⚡ One HLD concept. 60 seconds. Interview ready
Distributed Caching: Why Spread It Out?
Distributed caching spreads data across multiple servers for better performance and reliability.
⚡ One HLD concept. 60 seconds. Interview ready
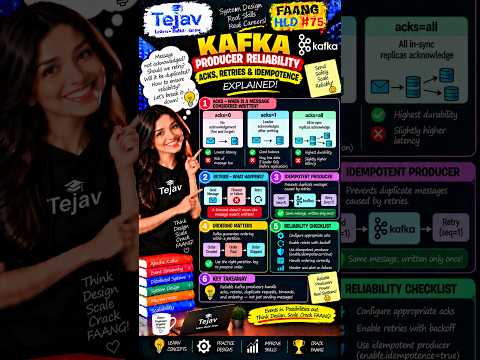
Kafka Producer Reliability: ACKs, Retries & Idempotence
Kafka producers use ACKs, retries, and idempotence to ensure reliable message delivery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Kafka Retries and Dead Letter Queue (DLQ)
Kafka uses retries and Dead Letter Queues to manage message processing failures.

⚡ One HLD concept. 60 seconds. Interview ready
Optimistic vs Pessimistic Locking in Database Management
Optimistic and pessimistic locking are strategies to manage database access during concurrent transactions.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Stateful Stream Processing: How Does It Remember?
Kafka uses state stores to remember previous events in stateful stream processing.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Invalidation: TTL vs Freshness Explained
Cache invalidation is about knowing when to refresh cached data.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replication and ISR: Ensuring Data Availability
Kafka uses replication and in-sync replicas to ensure data is always available.

⚡ One HLD concept. 60 seconds. Interview ready
Elasticsearch Pagination: Fixing Slow Page Searches
Deep pagination in Elasticsearch can slow down searches significantly, but there are efficient methods to handle it.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding the Retry Pattern in System Design
The retry pattern helps systems recover from temporary failures but can cause overload if misused.

⚡ One HLD concept. 60 seconds. Interview ready
Keep-Alive in Networking: Efficient HTTP Connections
Keep-Alive allows reusing HTTP connections to improve efficiency and reduce overhead.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.
⚡ One HLD concept. 60 seconds. Interview ready
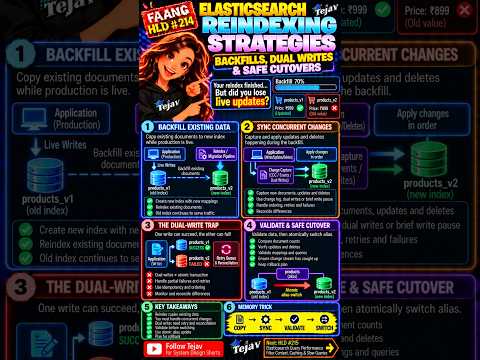
Elasticsearch Reindexing: Understanding the Dual-Write Trap
The dual-write trap in Elasticsearch can cause data inconsistency during reindexing.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Jitter in High-Level Design
Jitter helps spread out client retries to avoid traffic spikes.

⚡ One HLD concept. 60 seconds. Interview ready
Cache Eviction Policies: LRU, LFU, and FIFO Explained
Cache eviction policies determine which data to remove when caches are full.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.

⚡ One HLD concept. 60 seconds. Interview ready
Sync vs Async Replication: Choosing the Right Approach
Synchronous replication waits for confirmation from replicas, while asynchronous allows faster writes without waiting.

⚡ One HLD concept. 60 seconds. Interview ready
DNS Service Discovery: Is DNS Enough for Microservices?
DNS helps microservices find each other, but it has limitations that may require a service registry.