
I'm preparing for
🎛️ Narrow downsubject · level · topic▾
Results · 15 for “Disaster Recovery Planning”
← Front page✨ Smart search: matched by meaning, not just words

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Cross-Cluster Replication (CCR)
Elasticsearch CCR allows real-time data replication for faster disaster recovery.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding Elasticsearch Snapshots: Replicas vs Backups
Replicas keep your system available, while snapshots allow for data recovery.
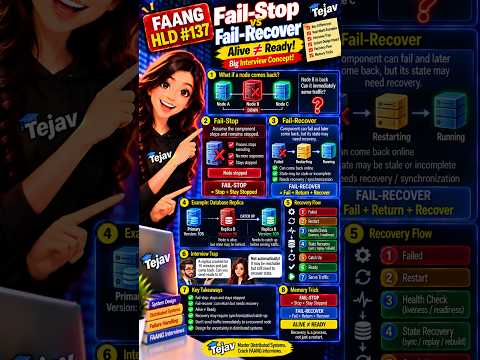
⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fail-Stop vs Fail-Recover Explained
Fail-stop means a system stops and stays down, while fail-recover means it can come back but needs to be ready.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Managing Dependency Failures in Distributed Systems
Dependency failures can disrupt applications, but resilience patterns can help manage them.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Crash Recovery: Resuming Processing Explained
Kafka consumers resume processing from the last committed offset after a crash.

⚡ One HLD concept. 60 seconds. Interview ready
Kafka Consumer Reprocessing: Safe Event Replay Strategies
Kafka consumer reprocessing involves safely replaying events to correct system states.

⚡ One HLD concept. 60 seconds. Interview ready
Cascading Failures in Distributed Systems Explained
Cascading failures occur when one service's failure impacts others, causing widespread issues.
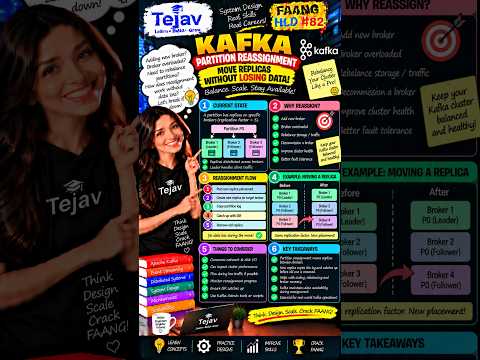
⚡ One HLD concept. 60 seconds. Interview ready
Kafka Partition Reassignment: Move Replicas Without Data Loss
Kafka Partition Reassignment moves replicas between brokers while keeping data safe.

⚡ One HLD concept. 60 seconds. Interview ready
HLD: Fallbacks Explained for System Design
Fallbacks allow systems to handle failures safely and maintain user experience.
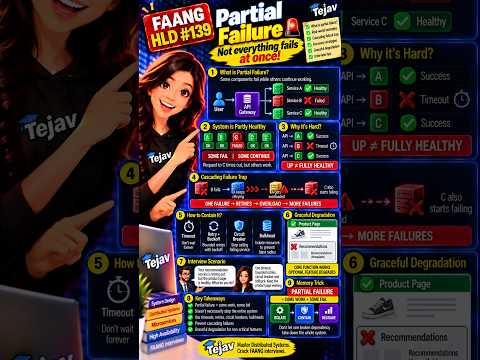
⚡ One HLD concept. 60 seconds. Interview ready
Understanding Partial Failure in Distributed Systems
Partial failure means some services fail while others keep running, impacting system reliability.

⚡ One HLD concept. 60 seconds. Interview ready
Graceful Degradation in System Design
Graceful degradation allows apps to function partially during service failures.
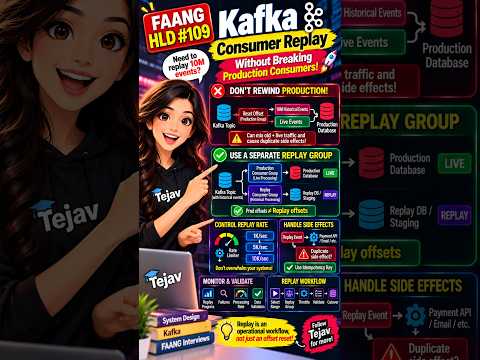
⚡ One HLD concept. 60 seconds. Interview ready
Kafka Replay Without Breaking Production: Safe Architecture
You can replay Kafka events safely by separating live and replay processes.
⚡ One HLD concept. 60 seconds. Interview ready
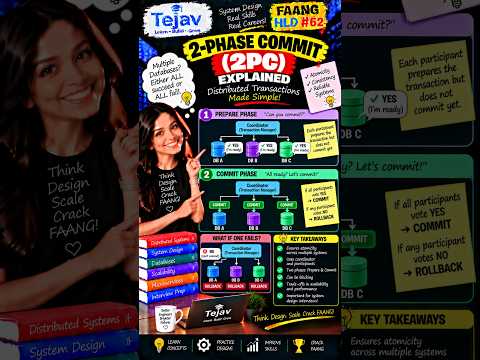
Understanding 2-Phase Commit in Distributed Transactions
2-Phase Commit helps maintain data consistency in transactions across multiple databases.

⚡ One HLD concept. 60 seconds. Interview ready
Understanding CAP Theorem: Trade-offs in Distributed Systems
The CAP Theorem explains the trade-offs in distributed systems during network failures.

⚡ One HLD concept. 60 seconds. Interview ready
Database Replication: Scale and Survive Failures
Database replication helps keep data available and allows systems to handle more read requests.